Browse categories
English
$
USD
Connect to your AI
Backend Developer and Local AI Specialist: Laravel, Python, RAG
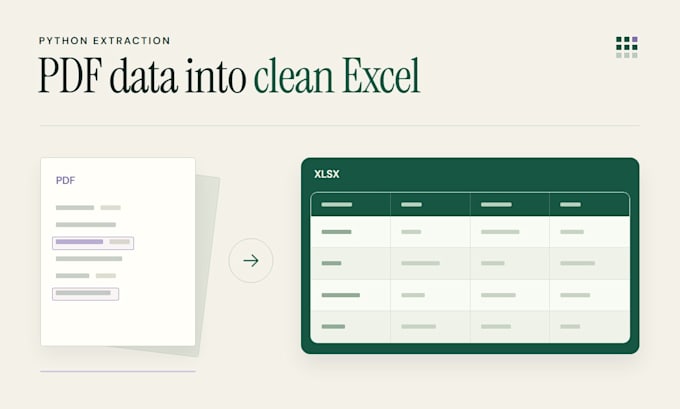
Turn repetitive PDF reports into a clean Excel or CSV file you can actually use.
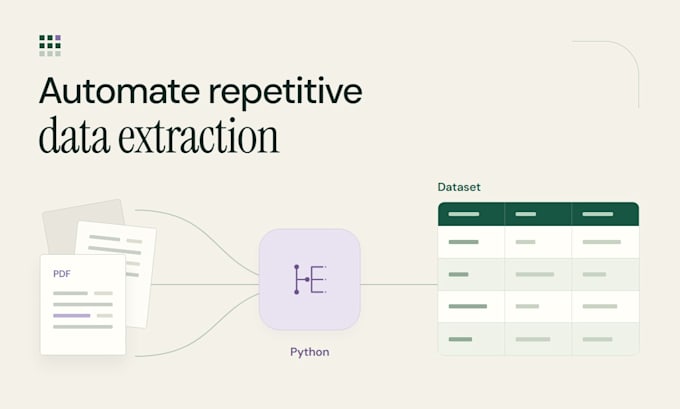
I build Python extraction workflows for readable, text-based PDFs with consistent layouts. You define the columns; I map the agreed fields, process the included batch, and check the output structure.
Basic covers up to 20 pages and one layout. Standard adds up to 70 pages, two layouts, and a reusable Python script. Premium covers up to 150 pages and three layouts, with agreed validation checks and run documentation. Field, file, and row limits apply.
You receive structured output, a short extraction summary, and a clear list of anything that needs review. Standard and Premium also include the source script. Outputs are checked against the agreed schema; PDF extraction can still need human review.
Please message me with a redacted sample of every layout and your target columns before ordering. Scans, handwriting, advanced OCR, changing templates, and complex business rules need a separate assessment.
Technology:
Excel
•
Google Sheets
•
Python
Which PDFs can you work with?
Readable, text-based PDFs with consistent field labels or table structures are the best fit. Send a redacted sample of every layout before ordering so I can assess the extraction and confirm the package.
Is this manual data entry?
The service uses Python to extract repeatable data structures. It is intended for recurring document formats, with a defined schema and checked output. Manual transcription of varied documents is outside this offer
What counts as a different layout?
A layout uses the same field labels, field positions, and table structure. Different values or dates are usually fine. A changed header structure, moved field, or new table arrangement may require separate extraction logic and count as another layout.
Will the result be 100% accurate?
No accuracy percentage is guaranteed. I review representative output, check the agreed structure, and flag detected exceptions. PDFs can contain missing text or unusual formatting, so you should review flagged values before relying on the data
Can you handle scanned PDFs or handwriting?
Scans, image-only PDFs, handwriting, advanced OCR, and low-quality documents need a separate assessment and custom quote. They are not included in these packages.