Browse categories
Explore
Fiverr Pro
English
$
USD
Need data from a website, a directory, an online catalog, or from hundreds of PDFs and invoices? I extract it and deliver a clean, ready-to-use dataset in Excel, CSV, JSON or Google Sheets.
Typical jobs:
- Product catalogs and price lists
- Business directories, listings and public registers
- Tables and line items from PDF invoices, reports or scanned documents
- Public statistics, open data and articles for analysis
- Price monitoring that re-runs automatically (Premium)
What you get:
- Deduplicated, cleaned and consistently formatted data
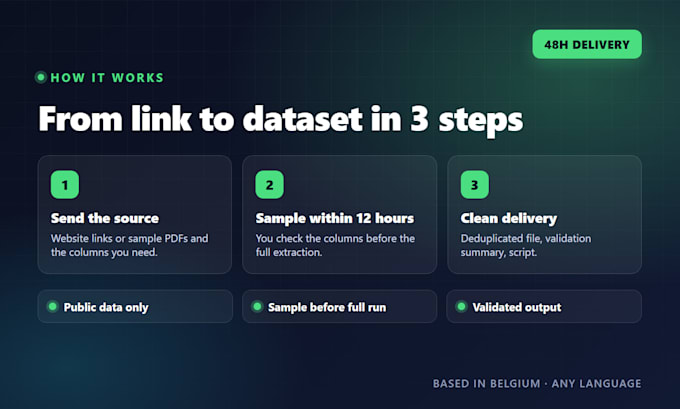
- Exactly the columns you asked for, with a sample sent within 12 hours
- A validation summary (rows collected, gaps, notes)
- A reusable Python script with instructions (Standard and Premium)
I work only with publicly accessible data, respecting website terms and privacy law: no personal-data harvesting, no login bypass, no CAPTCHA bypass.
Deliverables available in English, French, Dutch, German, Spanish, Turkish, Arabic and more.
Send me the link(s) or a sample file and I will confirm feasibility and the right package before you order.

Technology:
Python
•
Scrapy
•
Beautiful soup
•
Playwright
•
Pandas
Technique:
Automated
Can you scrape any website?
Most public websites, yes. Platforms whose terms forbid scraping (marketplaces, social networks, review sites) and login-walled sites are declined. Send the link before ordering: I confirm in writing what is possible, which columns and roughly how many rows you get. That message is the order scope.
What counts as one source?
One website (all its pages of the same type, e.g. every product page of a shop) or one batch of PDFs with the same layout.
What format do I receive?
Excel (.xlsx), CSV, JSON or Google Sheets, with the columns you specify.
Do you deliver the script?
Yes, in Standard and Premium, with instructions so you can run it again yourself. Scheduled scrapers (Premium) run on your own account, for example GitHub Actions or a small server; I set it up with you.
What about personal data?
From websites I do not collect personal data of individuals (private emails, phone numbers) or anything that breaches GDPR. Extracting data from your own documents, such as invoices, is fine.
Can you extract data from scanned PDFs?
Yes, including OCR for scans. Accuracy is validated on a sample first.
Any excluded projects?
Anything related to gambling, adult content, alcohol, music/entertainment, dating, interest-based lending/investment products, or school/university assignments meant to be submitted as your own work, and anything that violates a website terms.