Browse categories
Explore
Fiverr Pro
English
$
USD
AI Engineer LLM Fine Tuning with LoRA and QLoRA
I fine-tune 7B and 14B AI models on your data. Not prompt templates - real, fine-tuned LLMs trained on your questions and answers, tested before delivery, and shipped in the format you need.
What I do:
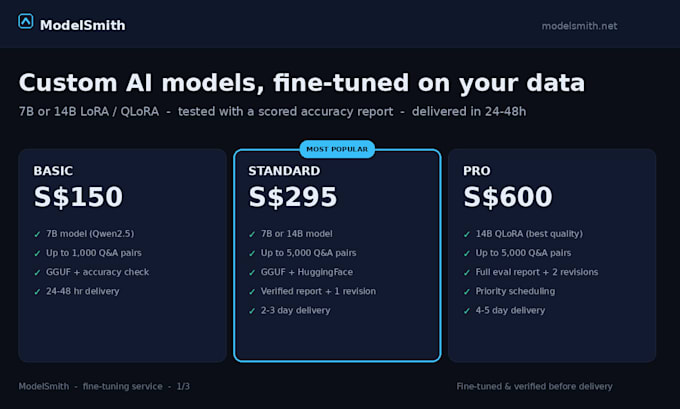
- LoRA / QLoRA fine-tuning of 7B or 14B models (Qwen2.5 by default)
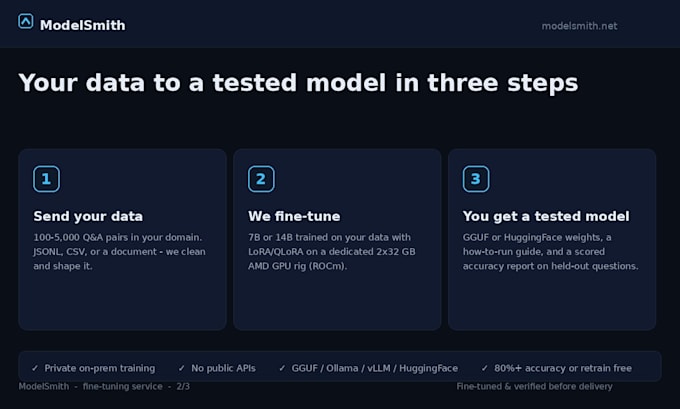
- Trained on 100 to 5,000 of your own Q and A pairs
- Verified with a scored accuracy report on held-out questions
- Delivered as GGUF (Ollama, llama.cpp) or HuggingFace (vLLM, Transformers)
Why it is different:
Most fine-tuning gigs hand you a file and say good luck. I test it first. Every model ships with an accuracy report on your own held-out data - 80 percent or higher, or I retrain free.
Privacy:
Training runs on a private 2x32 GB GPU rig. Your data never goes to a public API and is deleted on delivery unless you ask me to keep it.
Speed:
A 7B LoRA trains in under an hour of compute. Most projects deliver in 24 to 48 hours.
Send me your dataset and I will have a tested model ready in days.


Programming Language:
Python
•
Pytorch
•
Other
Data Type:
Text
•
Tabular Data
•
Other
AI Engine:
Llama
•
PyTorch
•
Other
What model do you use?
Qwen2.5-7B-Instruct by default for the 7B tier. Qwen2.5-14B-Instruct for 14B. Mistral and Llama models available on request.
What do I need to send you?
100 to 5,000 Q and A pairs in any format: JSONL, CSV, or even a document. I will clean and structure it.
How is this different from a prompt template or system prompt?
A prompt template instructs a generic model. A fine-tune changes the model weights so it knows your answers natively. Better accuracy, your voice, lower prompt overhead.
Is my data safe?
Yes. Training runs on a private local 2x32 GB GPU rig, not a public API. I delete the dataset on delivery unless you ask me to keep it.
What exactly do I receive?
Model weights (GGUF and/or HuggingFace), a how-to-run guide with exact commands for your runtime (Ollama, llama.cpp, vLLM), and a scored accuracy report.
What if the model does not work well?
Standard includes 1 free revision, Premium 2. If the held-out evaluation misses your accuracy target, I retrain at no cost.
How long does delivery take?
7B: 24-48 hours. 14B: 2-5 days. Turnaround starts once your dataset is confirmed.
Do I need my own GPU or hardware?
No. I handle all training on my rig. You only need hardware to run the final model (any CPU can run a 7B GGUF, or use Ollama).