Browse categories
Explore
Fiverr Pro
English
$
USD

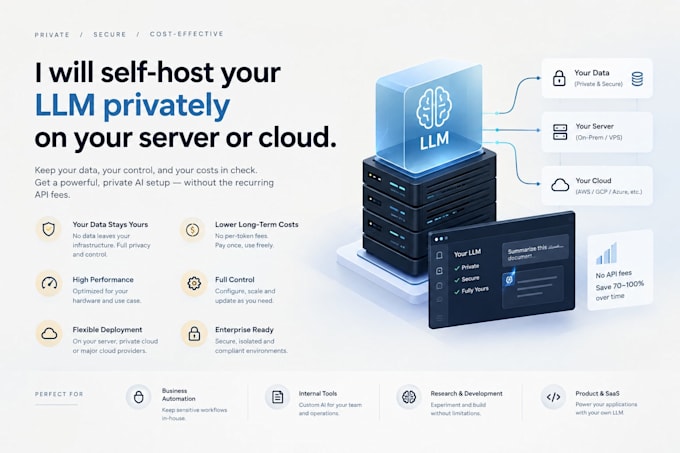
I will self-host your LLM privately on your own server or cloud
Running your LLM through a third-party API means your prompts and data pass through someone else's servers. If you need data privacy, predictable costs, or an offline/air gapped model, self-hosting is the answer. I set it up end-to-end.
I deploy open-weight models (Llama, Mistral, Qwen, DeepSeek, or your fine-tuned model) on your own VPS, dedicated server, or cloud GPU instance (AWS, Vultr, RunPod, Lambda Labs), and expose them through a clean OpenAI-compatible API endpoint you can plug straight into your app.
What you get:
I've set up production infrastructure on AWS (ECS, EC2, IAM) and run GPU-mounted Kubernetes workloads before this isn't my first server.
AI Engineer and Automation Specialist I LangChain, RAG I React, Node, DevOps
Languages
Do I need my own GPU?
No — I can help you provision a cloud GPU instance if you don't have one (cost is separate from the gig price).
Can you fine-tunning the model?
That's a separate service — this gig covers deployment/hosting of an existing or open-weight model.
Is my data really private?
Yes — once deployed, all inference runs on your infrastructure; nothing is sent to a third-party API.
