Browse categories
Explore
Fiverr Pro
English
$
USD
Certified Data Annotator, Computer Vision, ML and AI Data Training Expert
Level 1
Has met certain performance criteria and shows strong potential in the marketplace.
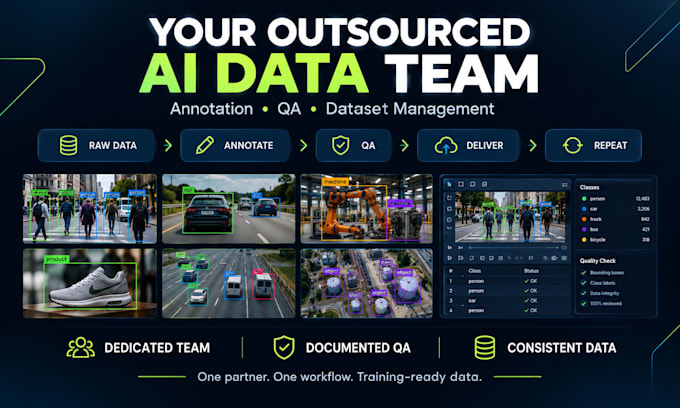
Most freelance annotation help is task-based: send images, get boxes back, you're still managing quality and scheduling. This is different, I take ownership of the workflow.
WHO THIS IS FOR
CV and AI/ML teams needing a reliable, ongoing annotation partner, not a single gig, but a team that scales with your batch sizes and stays consistent over weeks or months.
WHAT I MANAGE FOR YOU
PROVEN AT SCALE
I've run this for CV startups training production models on real footage, multi-week engagements across thousands of frames and dozens of batches, QA-approved, feeding fine-tuning.
HOW WE'D START
Send your guideline and a sample batch. I'll run it through the pipeline, review, annotate, QA, deliver, so you evaluate before committing.
In-house vs enterprise vs a leaner partner? Happy to talk.
Technique:
Manual
Tagging type:
Text
•
Image
•
Video
Can you handle ongoing, recurring batches, not just a one-time project?
Yes — this is built specifically for ongoing engagements. Delivery cadence and batch size are set based on what your model training schedule needs.
Do you only do bounding boxes, or other annotation types too?
Bounding box, polygon, keypoint, and video frame annotation, in CVAT or your preferred tool, exported to whatever format your pipeline uses.
What if our taxonomy has complex, condition-based labeling rules?
That's a core strength, multi-class taxonomies where labeling depends on context (not just "draw a box around X") are exactly the kind of guideline work this workflow is built to handle consistently across a team and across batches
How do you ensure quality across a whole team, not just one annotator?
Every batch goes through a documented QA pass before delivery, duplicate checks, boundary coordinate validation, and consistency checks plus error-pattern tracking across batches so the same mistake doesn't reappear in the next one.
