Browse categories
Explore
Fiverr Pro
English
$
USD
Full Stack Web Developer: WordPress, OCR, API Integration, Peptide Websites
Need to automate visual tracking, extract data, or launch an AI app?
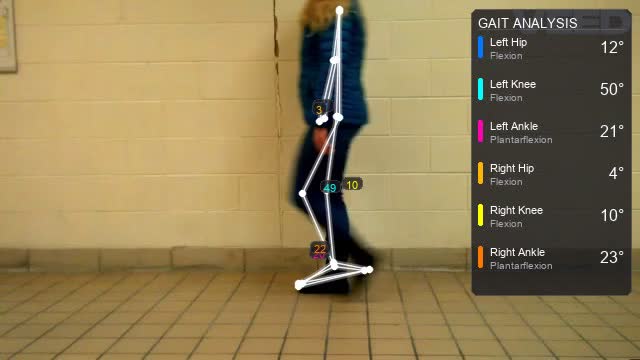
Manual video analysis and document handling cost your business time. I build high-performing AI computer vision and OCR systems to solve your bottlenecks and turn visual data into actionable insights.
Whether you need a standalone computer vision or object detection app or a data extraction pipeline, I deliver robust, deployment-ready software tailored to your workflow.
PROBLEMS I SOLVE:
TECH STACKS & TOOLS:
WHY CHOOSE THIS GIG?
Message me before ordering to discuss your dataset!
Programming language:
Python
•
MATLAB
•
SQL
•
Colab
•
MLflow
Tools:
Jupyter Notebook
•
OpenCV
•
TensorFlow
•
MLflow
•
CVAT
•
Colab
•
PyTorch
Frameworks:
Scikit-learn
•
Google ML Kit
•
SimpleCV
•
PyTorch
•
Panda
What do I need to provide to start building my computer vision or object detection app?
Please provide your dataset (images, videos, or document scans) and a clear explanation of what objects or text you want the AI computer vision and OCR system to track or extract. If you don't have data yet, I can assist you with data collection and custom framework setups.
Which deep learning frameworks and models do you use for development?
I primarily write clean Python AI scripts utilizing OpenCV for real-time video feeds, alongside PyTorch and TensorFlow for model training. For high-speed accuracy, I implement state-of-the-art architectures like YOLOv8 and YOLOv11 to ensure premium results.
Can your OCR system handle handwritten text or complex documents?
Yes, the intelligent OCR system is configured using robust engines (like Tesseract, EasyOCR, or cloud vision APIs) tailored to read multi-column layouts, digital invoices, and complex text fields, converting raw files into structured, searchable data pipelines.
Will the finalized application run locally, or can it be deployed to the cloud?
Both! Depending on your needs, I can deliver your solution as a lightweight desktop tool, package it into Docker containers for cloud servers (AWS/GCP), or build a fully interactive AI web app interface using modern python dashboard tools like Streamlit.
How do you guarantee the accuracy of object tracking and image segmentation?
Every pipeline undergoes strict validation testing using custom machine learning evaluation metrics. I rigorously tune confidence thresholds, eliminate false positives, and refine image segmentation masks until the system hits your required production accuracy.