Browse categories
Explore
Fiverr Pro
English
$
USD

Agency
CUSTOM LLM FINE-TUNING | PRIVATE AI
Generic AI models can hallucinate domain facts, miss your business context, or create privacy concerns.
THE SOLUTION
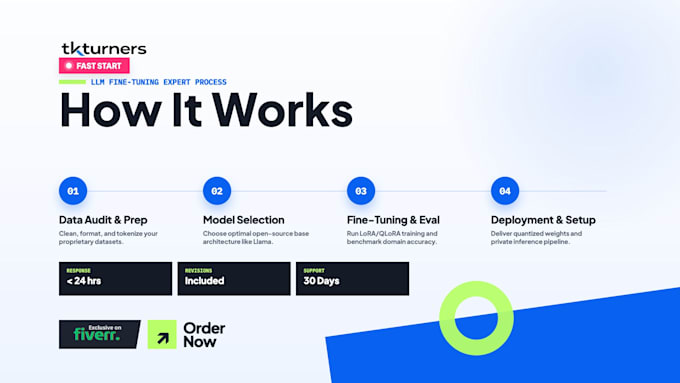
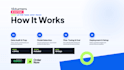
We fine-tune open-source LLMs like Llama 3, Mistral & Qwen on your proprietary data, workflows, and brand tone for specialized performance while keeping your data private.
WHY TKTURNERS
Full-stack AI engineering with LoRA/QLoRA, expert dataset curation, NDA compliance, and secure/air-gapped data handling.
WHAT WE DELIVER
QUALITY GUARANTEE
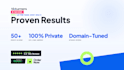
We iterate until the model meets the agreed benchmark metrics.
FREE AUDIT
Message before ordering for a free dataset audit & AI architecture roadmap.

Agency
20 employees
Languages

MEETOVO

S&D Moving

Empowering Confident Youth
Education Services
Why should I message you before placing an order?
Fine-tuning depends heavily on your dataset size, format, and target use case. Messaging first ensures we verify your data feasibility and pick the most cost-effective open-source architecture.
How do you ensure my proprietary business data stays confidential?
Your data is strictly yours. We execute enterprise NDAs, use private air-gapped compute environments, and delete all training data immediately after project completion.
Which open-source models can you fine-tune?
We work with top open-source models including Llama 3/3.1, Mistral/Mixtral, Qwen 2.5, Phi-3, Gemma 2, and specialized code/embedding models.
Who covers GPU compute and cloud training costs?
Compute costs (e.g., RunPod, Lambda Labs, AWS EC2, or Colab Pro) are paid directly by the client. We optimize training using QLoRA to keep compute costs typically under $10–$50.
What data format do I need to provide?
We accept JSONL, CSV, raw text, Markdown, PDFs, or instruction-response pairs. If your data is unstructured, we can clean and format it into high-quality instruction datasets.
In what format will my fine-tuned model be delivered?
We provide PEFT/LoRA adapter weights, merged safetensors, quantized GGUF files for Ollama/LM Studio, or a containerized vLLM/FastAPI service.
What access do you need from me to begin work?
We need your sample/full dataset and access to your preferred cloud GPU instance (RunPod, Hugging Face, or AWS) or local environment.
What is covered under revisions?
Revisions cover hyperparameter adjustments (learning rate, epochs, rank), re-evaluation on custom validation sets, and export format conversion.
Can you integrate the fine-tuned model into my existing web app or API?
Yes. As a full-stack engineering agency, we build FastAPI microservices, Docker containers, and Next.js/Node.js frontends to serve your model smoothly.Yes. As a full-stack engineering agency, we build FastAPI microservices, Docker containers, and Next.js/Node.js frontends to serve your model smoothl
Do you offer post-delivery support and maintenance?
Yes. The Premium tier includes 14 days of support. We also provide ongoing maintenance packages for retraining, dataset updates, and server scaling.