Browse categories
Explore
Fiverr Pro
English
$
USD
Messy web pages, feeds or Instagram accounts turned into one clean, deduplicated table you can query, refreshed on a schedule, with a dashboard or API on top.
The difference from a plain scraper: an AI step reads each item and fills the fields regexes cannot, such as category, price range, sentiment, entities, or the event date buried in a caption. Output is validated against the schema before it touches the database, so malformed answers fail loudly instead of polluting your data.
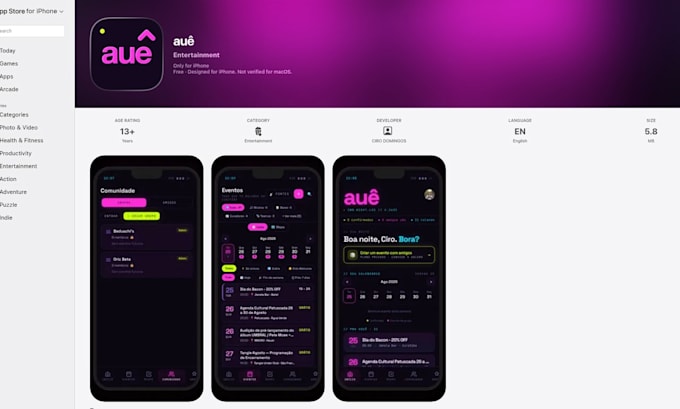
Proof: my events app ingests about 80 Instagram accounts through Apify and uses Claude to extract event fields from posts and images every day. My brand scraper does the same for brand attributes. Both links are on my profile.
What you get: the pipeline deployed on Railway or your host, the table in SQLite or Postgres, a Streamlit dashboard or a FastAPI endpoint, and the cost of every run recorded.
How we start: send two example pages and the columns you want. You get a sample table of 100 rows before the full run.
Not included: sites that forbid scraping in their terms, logins, captchas.
Technology:
Python
•
Google Sheets
•
Selenium
•
Playwright
•
Pandas
Technique:
Automated
Can it run on my server?
Yes, or on Railway under your account.
What does it cost to run?
Usually under $20 a month; every run logs its cost.