Browse categories
English
$
USD
Connect to your AI
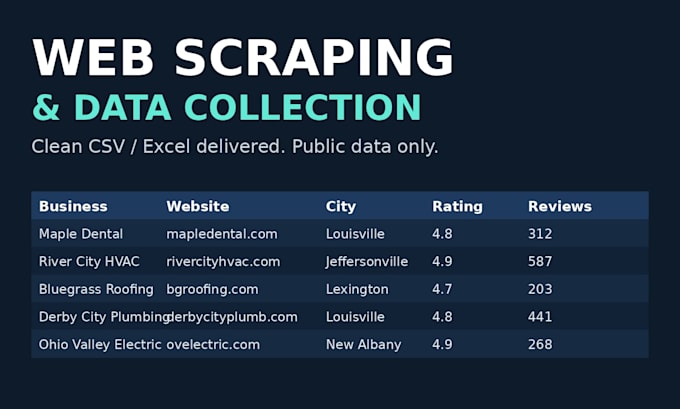
You name the site, I return the data as a clean spreadsheet. I scrape public websites, directories, and listings and deliver deduplicated records in Excel or CSV: product names, prices, business details, listings, or whatever fields the page shows. Difficult and large scrapes are the specialty, not raw data entry: paginated catalogs, multi-page directories, and messy output that needs cleaning before it is useful. Every delivery is checked for duplicate rows and broken fields before it reaches you, and I will tell you honestly how many real records a target holds before you order. Compliance is simple and strict: public data only. No login-walled sources, no private personal data, and no scraping a site asks us not to. If a target blocks collection or a job cannot be done inside the rules, I say so before any money moves. Message me your target site and the fields you need, and I will confirm the realistic record count and the right package first.
Technology:
Python
•
Google Sheets
•
Excel
•
Selenium
•
Playwright
Technique:
Automated
What do you need from me to start?
The target site or directory link, the fields you want from each record, and roughly how many records. I confirm the realistic count before you order, so you never pay for padding.
What sites can you scrape?
Public websites and directories. I do not scrape login-walled sources and I respect site terms. If a target cannot be collected inside those rules, I tell you before any money moves.
What format do I receive?
A clean Excel or CSV file, deduplicated, with columns in the order you ask for. Google Sheets opens both formats directly.
Can you repeat a pull monthly?
Yes. Repeat pulls are a common arrangement, and the Premium package includes re-run notes for exactly that. Message me for a standing repeat rate.
Can I see a sample first?
Yes. Send me the site and I will return a free sample of the first 50 rows in the exact delivery format before you order.
