Browse categories
Explore
Fiverr Pro
English
$
USD
Workflow Automation Expert LLMs Bots OCR
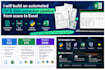
Stop paying by the hour for manual typing. I build automated pipelines that pull structured data straight out of scanned documents, PDFs, and images no manual re-typing required.
What I do:
Who this is for:
Tech I use: Python, Tesseract OCR, Pandas, OpenPyXL, PostgreSQL, DuckDB
What file formats can you work with?
A: Scanned PDFs, JPG/PNG images, and multi-page TIFF files. Send a sample and I'll confirm accuracy before you order.
What if my documents have messy or inconsistent layouts?
A: I build a custom parsing script around your specific layout. Send 2–3 sample files with your order so I can tailor it correctly.
Can you set this up so my team can run it ourselves later?
A: Yes — Standard and Premium packages include the script and basic instructions so you're not dependent on me for every new batch.
Do you guarantee 100% OCR accuracy?
A: OCR accuracy depends on scan quality. I include a validation/cleanup step to catch and flag likely errors, but very low-quality scans may need manual review.


