Browse categories
Explore
Fiverr Pro
English
$
USD


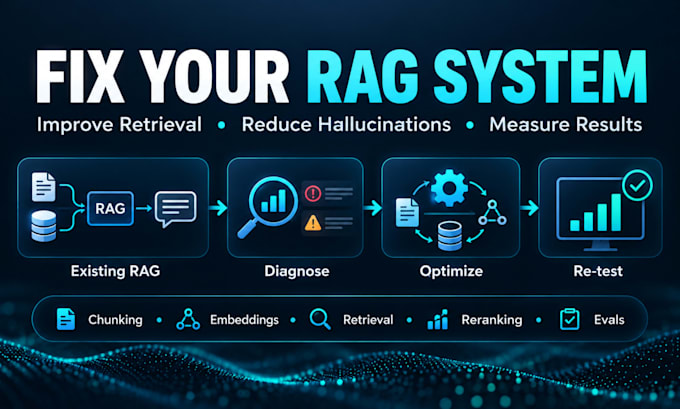
Is your RAG system retrieving the wrong documents, hallucinating, producing unreliable citations, or responding too slowly?
I will diagnose and optimize your existing RAG pipeline using measurable before/after testing not random prompt changes.
I can help improve:
- Chunking strategy
- Embeddings and vector search
- Retrieval accuracy
- Metadata filtering
- Hybrid search
- Reranking
- Prompt and context construction
- Hallucination reduction and grounding
- Citation quality
- Latency and token usage
- Vector database performance
- RAG evaluation
My process:
Measure -> Diagnose -> Fix -> Re-test -> Compare
I work with Python-based RAG systems, LangChain, LlamaIndex, FastAPI, OpenAI, Claude, local LLMs, Pinecone, Qdrant, Chroma, Weaviate, pgvector, and similar stacks.
You receive clear evidence of:
- What was causing the problem
- What was changed
- How the system performed before and after
- Any remaining limitations
This gig is for existing RAG systems. For large production systems, multiple integrations, or architecture rebuilds, please contact me before ordering.
AI and Data Science Engineer, RAG, MCP and LLM Automation
Languages
1. Do you build a new RAG system from scratch?
This Gig focuses on diagnosing and improving an existing RAG pipeline. New system development should be handled as a custom project.
2. Can you reduce hallucinations?
Yes. I investigate whether hallucinations come from retrieval, chunking, context construction, prompting, citations, or model behavior and fix the actual cause.
3. Can you improve retrieval accuracy?
Yes. I can review chunking, embeddings, vector search, metadata filters, hybrid search, reranking, and retrieval settings.
4. Can you work with Pinecone, Qdrant, Chroma, Weaviate, or pgvector?
Yes, depending on your current architecture and project requirements.
5. Can you optimize latency and API cost?
Yes. Latency, token usage, context size, unnecessary LLM calls, and retrieval efficiency can be reviewed and optimized.
6. Can you guarantee a specific accuracy improvement?
No. I first measure the current baseline and then report the actual improvement achieved on representative test cases.
7. What do you need from me to start?
Please provide your source code or repository, current RAG architecture, vector database, embedding model, sample knowledge-base documents, representative test questions, and a few examples of the failures you want fixed. If you have expected answers, logs, or evaluation results, those are also help