Browse categories
Explore
Fiverr Pro
English
$
USD


Are you looking to upgrade your application with high-performance semantic search, custom vector embeddings, and fast similarity matching?
I specialize in building production-grade vector database architectures, semantic search pipelines, and custom similarity algorithms using Python, FastAPI, Qdrant, and PostgreSQL (pgvector).
What I Offer:
Vector Database Integration: Setup and tuning of Qdrant, PostgreSQL (pgvector), Chroma, or FAISS.
Embedding Pipelines: Text chunking, token optimization, local (SentenceTransformers, E5, BGE) or cloud (OpenAI) models.
Custom Similarity Algorithms: Cosine Similarity, Euclidean Distance, and Dot Product calculations.
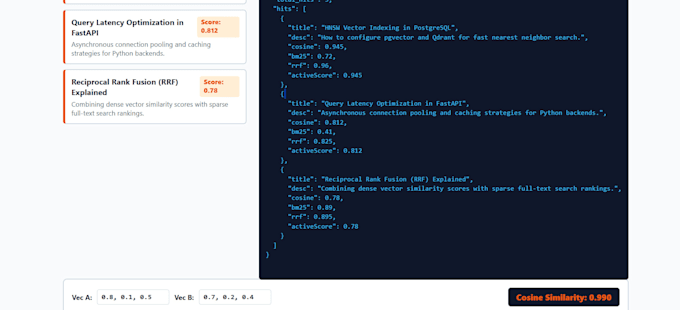
Hybrid Search: Fusion of traditional full-text search with dense vector retrieval using Reciprocal Rank Fusion (RRF).
Production APIs: Asynchronous REST endpoints engineered with Python, FastAPI, and Pydantic validation.
Tech Stack:
Python, FastAPI, Qdrant, PostgreSQL (pgvector), SentenceTransformers, Hugging Face, PyTorch, Docker.
Please send me a message before placing an order to discuss your dataset and requirements!
AI Backend Engineer RAG Vector Search
Languages
Why use Vector Search over traditional keyword matching?
Traditional search looks for exact word matches. Vector search analyzes semantic meaning, finding relevant context even when users use synonyms or different phrasing.
Can this run 100% locally for complete data privacy?
Yes. I can set up local embedding models (such as E5 or BGE via SentenceTransformers) and local vector stores (Qdrant or pgvector) so no data leaves your server.
What is Hybrid Search and why is it better?
Hybrid Search combines dense vector search (semantic meaning) with sparse keyword search (BM25 or PostgreSQL full-text) using Reciprocal Rank Fusion (RRF) for maximum precision.