I will custom rag pipeline for your documents

F
feichen314
F
feichen314
Feichen

About this gig

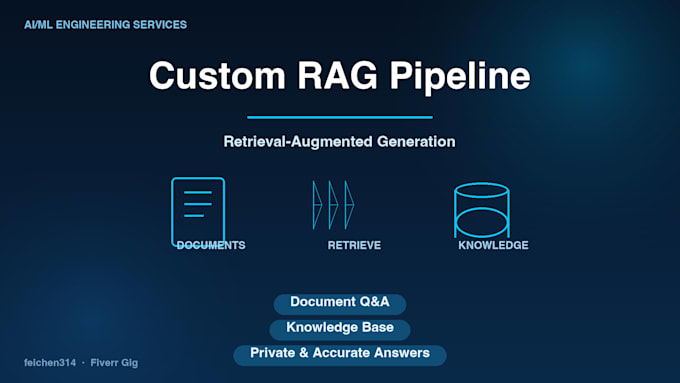
I build custom RAG (Retrieval-Augmented Generation) pipelines that turn your documents into an intelligent Q&A assistant. You provide the files (PDFs, Word docs, websites, markdown, etc.) and I design an end-to-end solution: chunking, embeddings, vector store, retrieval, and a clean chat interface grounded in your own knowledge base.


What I will deliver:

  • Custom RAG pipeline architecture for your documents
  • Vector database setup (Pinecone, Qdrant, Chroma, Weaviate, etc.)
  • Document ingestion and chunking strategy tuned to your content
  • Retrieval and reranking optimized for your use case
  • Source-cited answers to prevent hallucination
  • Clean API or chat UI integration


I work with your preferred stack (Python, LangChain/LlamaIndex, OpenAI or any other LLM provider) and deliver tested, production-ready code with clear documentation.

Get to know Feichen

Feichen

AI ML Engineer, LLM Fine tuning and Private Deployment Specialist

  • FromChina
  • Member sinceAug 2026
  • Avg. response time1 hour
  • Languages

    Chinese
AI/ML engineer specializing in LLM fine-tuning (LoRA/QLoRA) and private model deployment. Built a fact/opinion classification model via Qwen3-14B-4bit LoRA, achieving 99.7% accuracy on a 300-sample benchmark. I run a private 4-node Mac Mini M4 cluster - fine-tune and deploy your model locally, keeping your data 100% in your own infrastructure. Services: Custom LLM fine-tuning (LoRA/QLoRA), private/local model deployment & API serving (FastAPI), RAG pipelines, training data preparation & evaluation design. Fast, clear communication, English & Chinese.

My Portfolio

Other AI Development Services I Offer