Browse categories
English
$
USD
Connect to your AI


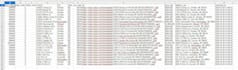

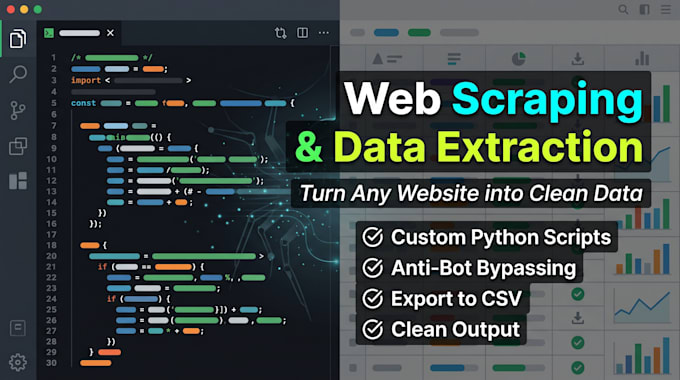
Need a fast, reliable web scraper or automated data extraction pipeline? You are in the right place!
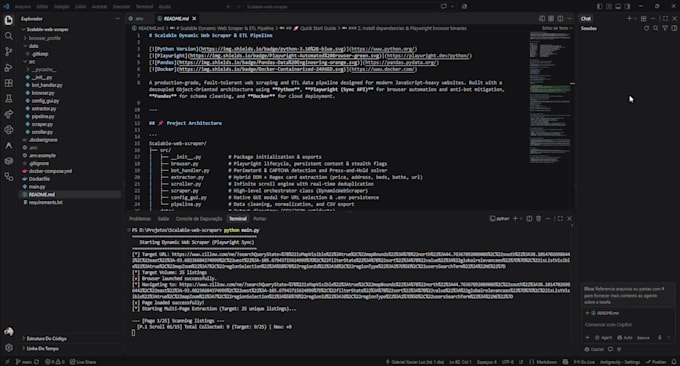
I build production-grade web scrapers in Python using Playwright, Pandas, and Docker. Unlike basic scripts that break on modern websites, my solutions handle complex dynamic JavaScript, infinite scroll feeds, and anti-bot defenses.
What I Deliver: Dynamic JS Scraping: Single-page apps, infinite scroll, and lazy-loaded items. Anti-Bot & CAPTCHA Mitigation: Bypasses PerimeterX, Cloudflare, and challenge overlays using persistent cookies and humanized browser mechanics. Automated Data Cleaning (Pandas): Normalizes raw text into clean numbers, splits addresses, and removes duplicates. Multi-Page Traversal: Automated pagination to extract high-volume datasets. Clean Formats: Excel-ready CSV, JSON, or Google Sheets. Docker Ready: 1-click containerized deployment for local PCs or cloud servers (AWS/GCP).
Use Cases: Real Estate listings, E-Commerce pricing, B2B directories.
️Please message me with your target URL and requirements before placing an order!
Python Developer, Automation and Data Processing
Languages
Why should I message you before placing an order?
Every website has its own unique structure, dynamic JavaScript behavior, and anti-bot security. Reviewing your target website URL beforehand allows me to verify feasibility, check the required data fields, and offer you the most cost-effective package.
Can you scrape websites with CAPTCHAs, Cloudflare, or PerimeterX?
Yes! I use Playwright with persistent browser sessions, humanized mouse mechanics, and stealth flag configurations specifically engineered to bypass modern bot verification overlays and dynamic challenges.
In what formats will I receive the extracted data?
I provide clean, formatted data in Excel-ready CSV (properly encoded to avoid formatting errors), XLSX, JSON, or direct sync to Google Sheets. You also receive the complete Python source code and documentation.
What do I need to run this scraper on my own computer?
You have two easy options: you can run it locally with standard Python, OR use the included Docker setup (docker compose up) to run the entire scraper in 1 single command with zero setup or dependency installation required!
Can this scraper run automatically on a schedule in the cloud?
Yes! With the included Dockerfile, the scraper is 100% cloud-ready and can be deployed to AWS, Google Cloud Run, or DigitalOcean to run automatically on scheduled cron jobs (e.g., daily or weekly).