Browse categories
Explore
Fiverr Pro
English
$
USD

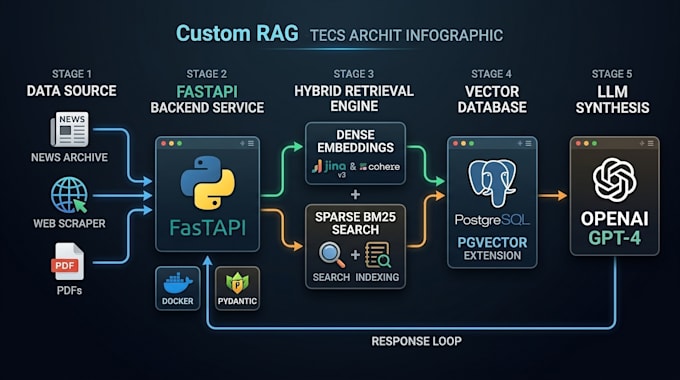

Are you looking to integrate custom data into Large Language Models (LLMs) with high precision and low latency?
I build robust, production-ready Retrieval-Augmented Generation (RAG) systems and Agentic AI workflows tailored for your business needs.
What I Offer:
- Custom RAG Architecture: Document chunking, embedding generation (Cohere, OpenAI, Jina), and vector storage.
- Vector Databases: PostgreSQL (pgvector), Pinecone, or Qdrant integration.
- Hybrid Search: Dense + Sparse search for maximum retrieval accuracy.
- Backend Integration: High-performance REST APIs built with Python & FastAPI.
- Autonomous AI Agents: LangGraph workflows for complex, multi-step tasks.
- Clean Code & Docs: Fully typed (Pydantic), documented, and Dockerized code.
Tech Stack:
Python | FastAPI | PostgreSQL / pgvector | LangChain / LangGraph | Docker | OpenAI / Cohere
How We Work:
1. Contact me with your requirements before placing an order.
2. We define the project scope, tech stack, and deliverables.
3. I build, test, and deliver the system with step-by-step instructions.
Let's turn your data into an intelligent AI system. Send me a message to get started!
Software Engineer
Languages
Can you deploy the RAG system to my server?
Yes, I provide Dockerized setups and deployment guides for cloud platforms like AWS, DigitalOcean, or Hetzner.
Do I need my own API keys?
Yes, you will need your own API keys for LLM services (e.g., OpenAI, Cohere, Anthropic). I can guide you through setting them up.
