Browse categories
Explore
Fiverr Pro
English
$
USD

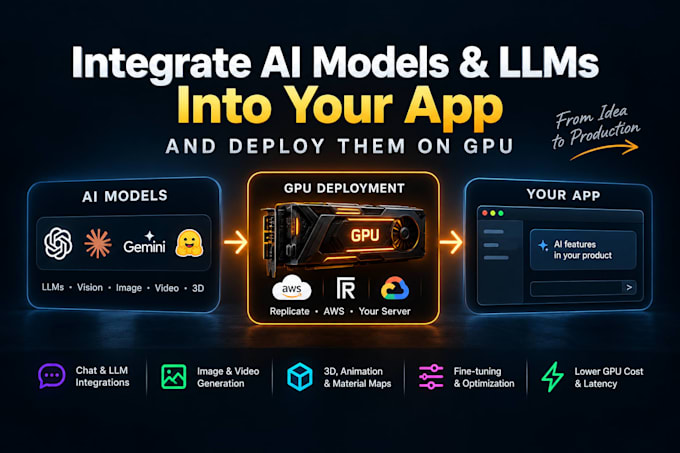
Got an AI feature that works in a demo but breaks in production? I build and ship AI integrations that hold up under real users.
For the last 5 years, I've worked as an AI engineer building production pipelines for gaming and real-time 3D: LLMs, video matting, camera tracking, animation and material-map models, deployed on cloud GPUs and wired into live web apps.
What I can do for you:
- Integrate OpenAI, Claude, Gemini or open-source models into your app
- Deploy custom or Hugging Face models on Replicate, AWS or your own GPU server
- Build generative AI pipelines for image, video and 3D
- Fine-tune existing models on your data
- Connect it all to your Next.js, React or Python backend
- Reduce GPU cost and latency
Why me:
I don't just call an API. I've trained, optimised, and maintained models in production and handled both frontend and backend integration.
You get clean source code, a working endpoint, documentation and a handover call.
Message me before ordering with your use case and stack so I can recommend the right package.
Full Stack Blockchain and Gen AI developer
Languages
Which AI models can you integrate?
Hosted APIs such as OpenAI, Claude and Gemini. Hosted platforms such as Replicate and Hugging Face. Also open-source or custom PyTorch models, including image, video, LLM and computer vision models.
Do I need my own GPU or cloud account?
No. I can deploy to Replicate or AWS under your account, so you own the infrastructure and billing. If you already have a GPU server, I can deploy there.
Can you work with my existing codebase?
Yes. I regularly integrate into existing Next.js, React and Python backends, and I adapt to your structure rather than rewriting it.
Will I own the code?
Yes. You receive full source code, deployment configs and documentation.
How do you keep GPU costs down?
I choose the right GPU tier and use queuing, autoscaling and cold-start tuning. Where quality allows, I also optimize or quantize the model.
Can you fine-tune a model for my use case?
Yes, if you have suitable data. I'll assess your dataset first and tell you honestly whether fine-tuning or a better prompt or pipeline is the smarter choice.
