Browse categories
Explore
Fiverr Pro
English
$
USD


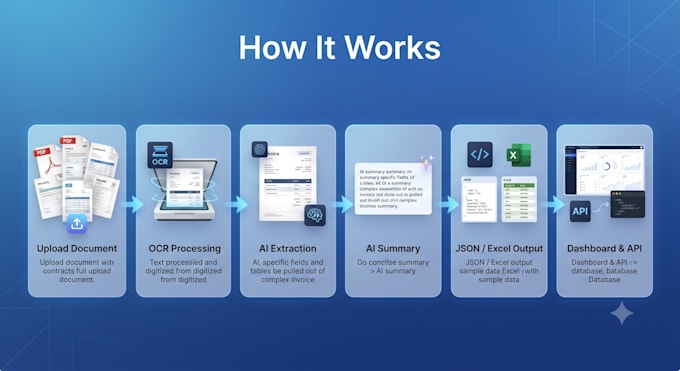
Turn stacks of PDFs, contracts, or scanned documents into structured, usable data.
I build AI document-intelligence pipelines the same kind of system I built for ShieldScan AI, a legal contract-risk analyzer that reads contracts, extracts clauses, flags risk, and generates plain-English summaries.
This gig is for you if:
What I build:
Tools: Python, Tesseract OCR, PyMuPDF, pdfplumber, LLM pipelines (open-source/API), FastAPI, streamlit(UI)
Send me a sample document (redact anything sensitive) before ordering and I'll confirm exactly what's extractable.
AI, ML Engineer specializing in LLM Automation and Document Intelligence
Languages
My documents are confidential — is that a problem?
No — I can work with redacted samples and don't retain your data after delivery.
Do you handle scanned/low-quality PDFs?
Yes, OCR is included where needed, though accuracy depends on scan quality — happy to test a sample first.
Can you build a custom document extraction solution for my business?
Yes. Every project is customized based on your document type, required fields, workflow, and desired output format.
Which document types do you support?
I can work with contracts, invoices, receipts, resumes, forms, reports, and most structured or semi-structured PDFs and images.