Browse categories
English
$
USD
Connect to your AI
AI Engineer : Machine Learning , Gen AI , Optimisation
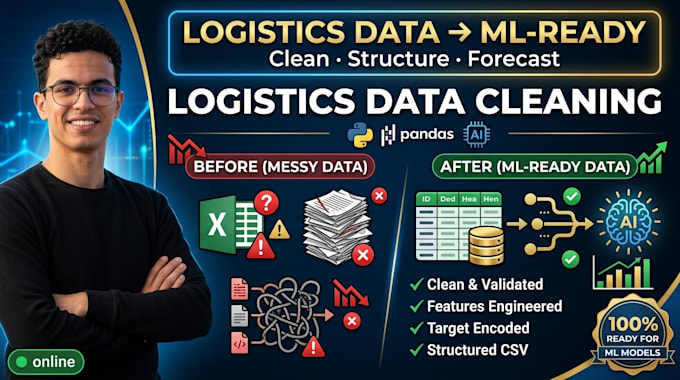
Are messy spreadsheets stopping you from training your ML models?
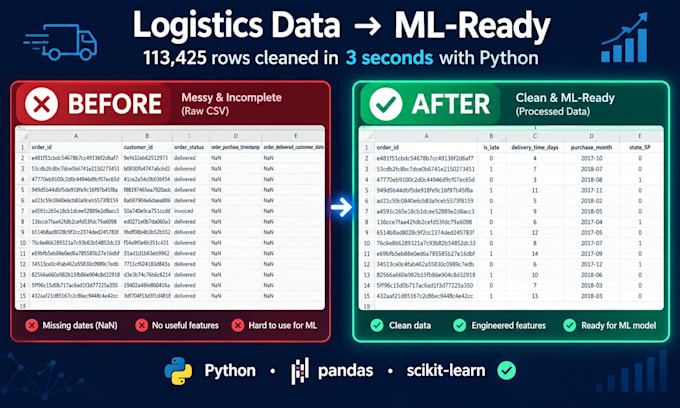
Unstructured delivery logs, inconsistent warehouse records, and missing inventory values will ruin your Machine Learning accuracy. I help logistics businesses and data teams transform raw, chaotic operational data into clean, ML-ready datasets.
What I can do for your logistics data:
What you will receive:
Tools I use: Python, Pandas, NumPy, Scikit-Learn.
Message me before placing an order so we can discuss your dataset size and specific goals!
What file formats do you accept?
CSV, Excel (.xlsx, .xls), JSON, Parquet, and most tabular formats. Just send me your file and I'll confirm.
What does "ML-ready" mean?
Your dataset will be ready to feed directly into a Machine Learning model: clean values, encoded categories, normalized features, and no missing data.
Do I get the Python code?
Yes! Every order includes the fully commented Python script (pandas, numpy, scikit-learn) so you can reproduce the process yourself.
How do you handle my data privacy?
Your data is 100% confidential. I never share, store, or reuse your files. I can sign an NDA if needed.
Can you handle large logistics datasets?
Yes, up to 1 million rows depending on the package. Contact me first for datasets over 100,000 rows.