Browse categories
Explore
Fiverr Pro
English
$
USD
AI coding agents can produce convincing output that still misses instructions, breaks existing behavior, or passes only shallow checks.
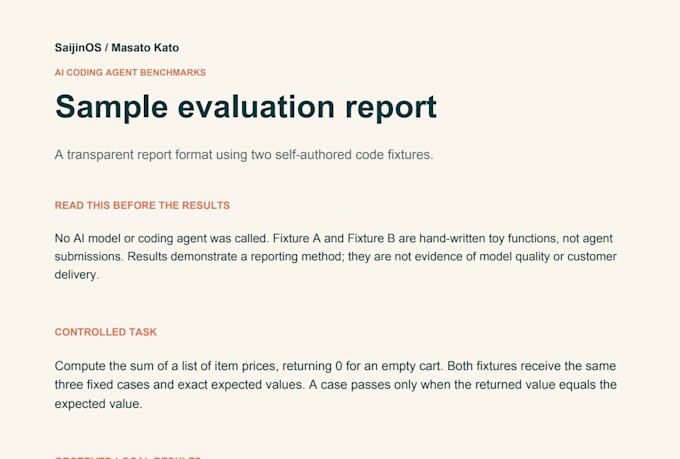
I will benchmark a bounded agent run against your supplied task and repository, execute relevant tests where feasible, and return an evidence-based report.
You will receive:
scope and test environment
pass, fail, and unknown findings
reproduction steps and test evidence
instruction-following notes
regressions and edge cases
recommendations clearly separated from verified results
Good fit for Codex, Copilot, Claude-style coding agents, autonomous repository tasks, and patch or PR comparisons.
Please provide the repository or relevant files, task or prompt, agent output or patch, available run logs, setup steps, and expected result. Remove API keys, passwords, personal data, and other secrets before sending.
This service is testing and reporting only. It does not include a formal security audit, penetration test, unlimited repository review, production deployment, or a guarantee of model quality.


Testing application:
Software
Development technology:
JavaScript
•
Python
•
TypeScript
Device:
PC
•
Linux
What do you need from me?
Please send the repository or relevant files, task or prompt, agent output or patch, setup steps, and expected result. Remove all secrets first.
Do you rank AI coding agents globally?
No. The report applies only to the supplied tasks, repository, environment, and evidence. Unknown items stay clearly marked as unknown.
Will you fix the code too?
This Gig covers testing and reporting. Code fixes can be discussed as a separate custom offer after the findings are confirmed.