Browse categories
Explore
Fiverr Pro
English
$
USD
Bad data is the most common reason a detection model fails. I clean, convert and validate your object detection dataset so it is ready to train.
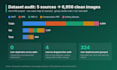
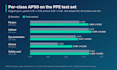
Background: for my PPE safety detection project I merged 5 public sources into one clean 6,956-image dataset: unified class names, removed duplicates, checked train/test leakage and fixed broken labels. Together with method comparisons, mAP50 rose from 0.674 to 0.753 on an 808-image test set.
I can:
What you get:
Note: drawing new labels from scratch is not included. Message me for a quote.
Technique:
Automated
Tagging type:
Image
•
Video
Do you label new images?
Not in this gig. I fix, convert and validate existing labels. New annotation from scratch is quoted separately, so message me with your volume.
Is my data kept private?
Yes. I use your data only for your order, never share it, and delete it after delivery if you ask.
Which YOLO versions are supported?
The YOLO TXT format works with YOLOv5, YOLOv8 and YOLO11 (Ultralytics). I also deliver a ready data.yaml file.
Can you convert Roboflow, CVAT or Label Studio exports?
Yes. Send the export as it is (YOLO TXT, COCO JSON, Pascal VOC XML, CVAT or Label Studio). I convert it to your target format, check that every box still matches its image, and give you a data.yaml ready for Ultralytics training.
How do you find bad labels?
Automatic checks first: boxes outside the image, zero-size or duplicate boxes, unknown class IDs, empty label files, and exact or near-duplicate images across splits. Then I look at a visual sample of every class. You get a CSV listing every issue found.


