Browse categories
Explore
Fiverr Pro
English
$
USD
Data Analyst Machine Learning Enthusiast
Your model is only as good as the data you feed it. I make sure that data is actually ready.
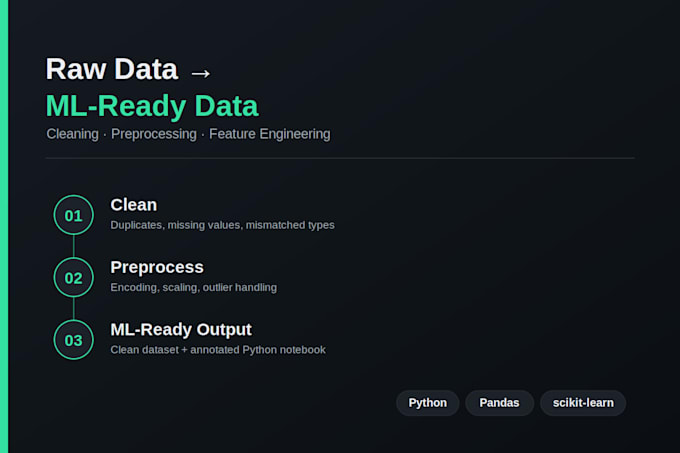
I clean, preprocess, and prepare datasets specifically for machine learning use not just tidied-up spreadsheets, but data that's genuinely ready to go into a model: properly encoded, scaled, missing values handled with a defensible strategy, and documented so you understand exactly what was done and why.
What you get:
Great for: students and researchers prepping data for a thesis or paper, startups building their first ML pipeline, data scientists who want the grunt work off their plate, Kaggle competitors short on time.
How it works:
_khk6yj.jpg)
Technology:
Excel
•
Google Sheets
•
Python
•
SAS
What format should I send my data in?
CSV, Excel, or JSON all work. If it's coming from a database or API, tell me and we can figure out the best export.
Will you build me a full ML model?
Baseline models are included in Premium as a data-quality check, not a production model. Full model development is a separate scope — message me.
How do you handle missing data?
Depends on the data and your use case — I'll choose (and explain) between deletion, mean/median imputation, or more advanced methods like KNN imputation, and tell you the trade-offs.
Can you work with datasets larger than 50,000 rows?
Yes, message me first for a custom quote — larger datasets are priced based on complexity, not just row count.