Browse categories
Explore
Fiverr Pro
English
$
USD
Your RAG chatbot looked fine in the demo. Then real users started asking real questions, and now it gives wrong answers with full confidence.
Usually the model isn't the problem. It's retrieval, chunking, or text that came out of OCR broken. I find out which one, with numbers instead of guesses.
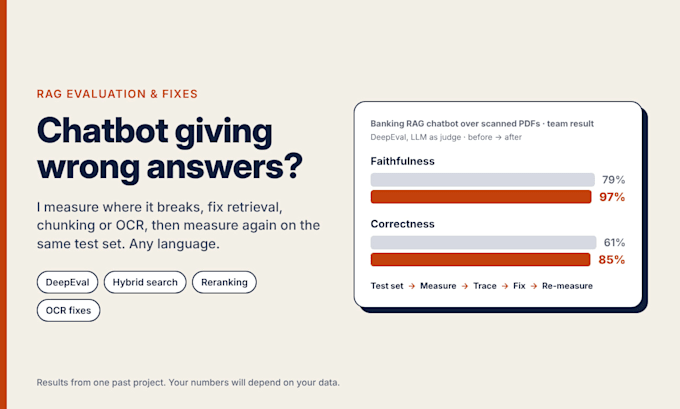
This is the work I know best. On a banking chatbot over scanned PDFs at GBG, we measured faithfulness at 79%. After fixing OCR and adding hybrid search, reranking and query rewriting, it reached 97%, and correctness went from 61% to 85% (DeepEval, LLM as judge).
How it works:
1. I build a test set from your documents and real user questions
2. I score faithfulness, correctness and retrieval quality
3. I trace each failure to its cause: parsing, chunking, search, ranking or prompt
4. You get a fix plan, or I make the fixes and score it again
You get a short report with before and after numbers on the same test set. I don't promise a specific number, since it depends on your data.
Works with LangChain, LlamaIndex or plain Python pipelines, in any language your documents are in.
Send me a few examples of bad answers. That's often enough for me to tell you where I'd look first.
AI Engineer building RAG systems, LLM agents and Arabic NLP
Languages
Do you need access to my code?
For the audit, a working API endpoint or read access is enough. To make fixes I need the code, ideally a private Git repo you invite me to. I don't need production passwords.
Can you promise a specific accuracy number?
No, and I'd be careful with anyone who does. It depends on your documents and questions. What I promise is honest before and after scores on the same test set, so you can see exactly what improved.
Which tools do you use for evaluation?
Mostly DeepEval with an LLM judge, plus checks on whether the right chunks were retrieved. If you already use RAGAS or your own setup, I can work with that.
Does the language of my documents matter?
The process is the same. Language mostly affects OCR, text splitting and search quality, and I check those specifically. I've worked most with Arabic and English. Tell me yours and I'll say honestly if it's a fit.
What if the real fix is a different architecture?
Then the report says so, with a rough estimate, before I write any code. You decide what happens next.
