Browse categories
Explore
Fiverr Pro
English
$
USD
Please message me before placing an order - send one sample document and I'll confirm what's possible.
Still retyping numbers from PDFs by hand? Invoices, contracts, tender packs, financial statements: one misread figure costs more than the whole extraction.
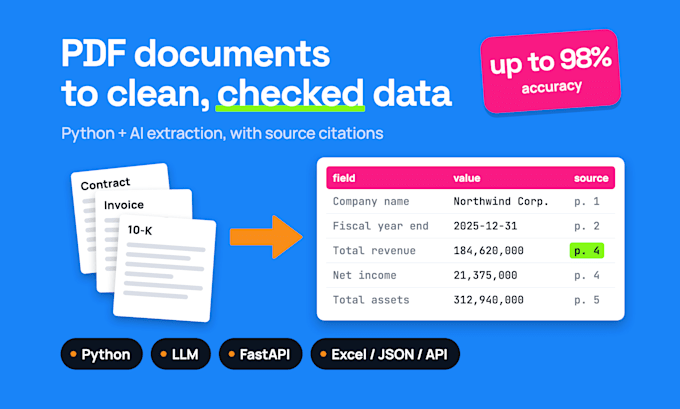
I build Python pipelines that turn your documents into clean tables - and show where every value came from, so you can check it instead of trusting it.
What you get:
Why me:
Not a fit for one-off copy-paste jobs you can do with ChatGPT.
Message me with a sample document and what you need out of it.
Python AI developer, over 12 years in IT, document AI and RAG in production
Languages
Why should you choose me?
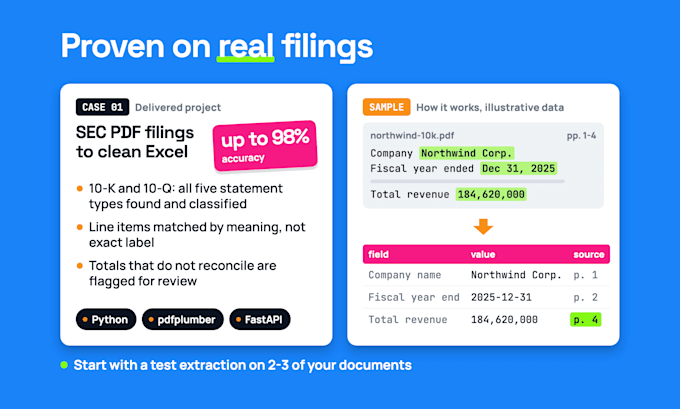
I build extraction you can verify: every value keeps its source page, and values the system is not sure about are flagged, not guessed. Proof: SEC 10-K/10-Q statements extracted to Excel at up to 98% accuracy, 12+ years in IT.
What's included?
The package deliverables, the source code (Docker included), an accuracy report on your own sample documents, and a short written handover.
What's not included?
Manual data entry, hosting costs, LLM API fees, and document types not agreed in the order. Extra document types can be added later as an extra.
Is my data safe?
Yes. I'm happy to sign your NDA before you share any documents. I use your files only for this order and delete them after delivery.
Can you test on my own documents before I order the full build?
Yes, that is what the Basic package is for: I run the extraction on 2-3 of your own documents and send an accuracy report and a plan. You decide on the full build only after you see real numbers.
How accurate will it be, and how do you measure it?
It depends on your documents, so I measure it instead of promising it: each extracted field is compared with the correct value on your samples, and you get the accuracy per field in the report.
Do you handle scanned PDFs (OCR)?
Yes. Text PDFs are read directly; scanned PDFs go through OCR. Scan quality affects accuracy, so scanned PDFs are tested first in the Basic package on your own files, before you commit to the full build.
Can you extract tables from PDFs?
Yes. Tables are the core of my SEC 10-K/10-Q work (financial statements). Each table comes out as rows and columns in Excel, CSV or JSON, with the source page kept for every value.
What output formats do you deliver?
Excel, CSV or JSON by default. With the Export To Sheet & DB extra, the data goes straight to your Google Sheet or database.
Can it run on my own server?
Yes. The Premium package ships in Docker, so the pipeline runs on your own server and your documents stay with you.