Browse categories
Explore
Fiverr Pro
English
$
USD

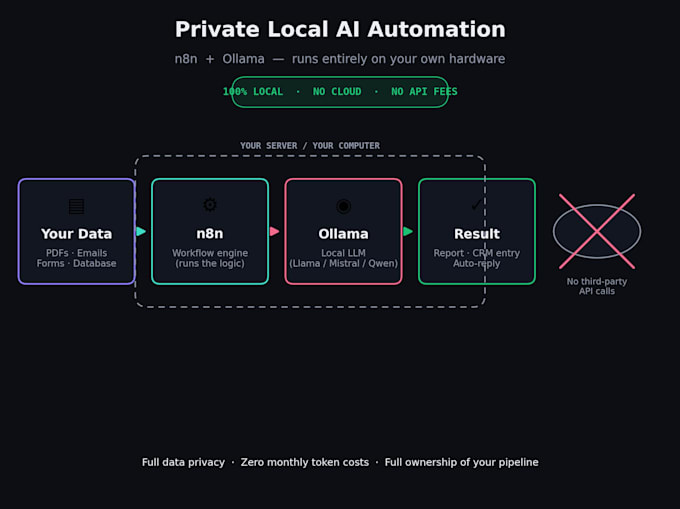

Stop paying monthly OpenAI fees protect your data with 100% Private Local AI!
Want AI automation without privacy risks or expensive token fees? I build Self-Hosted AI Systems using n8n + Ollama, running entirely on your hardware or private server.
Why Local AI?
100% Data Privacy nothing leaves your infrastructure
Zero API costs unlimited use of Llama 3, Mistral, Qwen, DeepSeek
Full ownership of your server, workflows & LLM parameters
What I Build:
How We Work:
1️ Discovery define goals & security needs
2️ Setup configure n8n + Ollama on your hardware/VPS
3️ Build design, test, optimize your AI logic
4️ Handover full docs + video walkthrough
AI Automation and Private LLM Specialist,n8n and Ollama Expert
Languages
Do I need powerful hardware to run this locally?
It depends on the AI model size. Smaller models run fine on a modern CPU or a mid-range GPU. For larger models or faster response times, a GPU (even a consumer one like an RTX 3060+) is recommended. I'll review your specs during Discovery and recommend the right model for your setup — no guesswork
I don't have a server — can you still help me?
Yes. If you don't have local hardware or a VPS, I can help you set one up (e.g., Hetzner, DigitalOcean, Contabo) as part of the project, or recommend a provider that fits your budget and needs.
Will my data really stay private?
Yes — with this setup, your data never leaves your own infrastructure. Unlike cloud AI APIs (OpenAI, etc.), there are no external calls sending your data to a third party. Everything runs locally.
Is a local open-source model (Llama, Mistral, Qwen) as good as ChatGPT/GPT-4?
For well-scoped business tasks (document extraction, lead scoring, internal Q&A), local models perform very well and are often "good enough" or better once tuned to your use case. They're not meant to replace general-purpose chatbots for every task
What happens after delivery — can I make changes myself?
Yes. You'll receive full documentation and a video walkthrough explaining how the workflow works, so you (or your team) can make basic adjustments independently. I'm also available for ongoing support/maintenance if you prefer not to manage it yourself.
How long does delivery take?
Delivery time depends on the package and project complexity — see the pricing tiers above. Complex integrations (database, fine-tuning) take longer and are reflected in the Standard/Premium packages.
What if the model doesn't understand my documents/data well enough?
That's exactly what the Discovery phase is for — we test with a sample of your real data early on, so we catch accuracy issues before full delivery, not after.
Do you offer ongoing maintenance after the project is delivered?
Yes, this can be arranged separately as a monthly retainer if you'd like me to keep maintaining, updating, or extending your workflows after handover.
