Browse categories
Explore
Fiverr Pro
English
$
USD


I will build a custom AI RAG chatbot that can understand and answer questions from your documents.
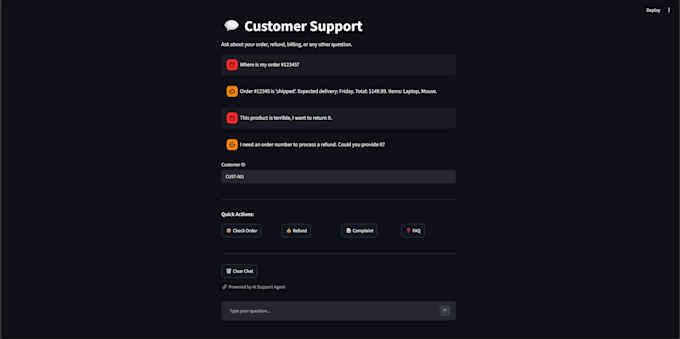
Whether you need an AI assistant for company knowledge, technical documentation, manuals, policies, reports, or research files, I can build a solution tailored to your requirements.
What I can build:
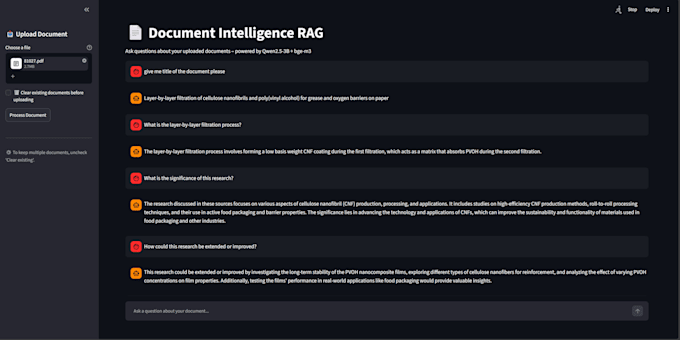
I use retrieval-augmented generation (RAG) to retrieve relevant information from your documents before generating answers, helping reduce unsupported responses and improving answer reliability.
You can use the system for:
I can build a simple prototype or a more advanced RAG application depending on your requirements.
Please contact me before ordering so I can understand your documents, expected features, and recommend the right solution.
Machine Learning Engineer
Languages
What types of documents can you process?
I can work with PDF, DOCX, TXT, PNG, and JPG files. OCR can be added for scanned documents and images.
Can you build a chatbot for my company documents?
Yes. I can build a private RAG chatbot that searches your documents and provides answers based on the relevant content.
Will the chatbot provide sources for its answers?
Yes. Source citations can be included so users can see which document content was used to generate an answer.
Can you integrate the AI into my existing application?
Yes. I can integrate the RAG system with an existing application or provide a FastAPI backend/API depending on the package and requirements.
Can you use my preferred AI model?
Yes. I can work with suitable Hugging Face/local models or API-based LLMs depending on your requirements.
Can you build OCR for scanned PDFs?
Yes. OCR can be included to extract text from scanned PDFs and images.
Can you handle large document collections?
Yes. I can design the retrieval pipeline for larger document collections. Please contact me first so I can assess the requirements.
Can you deploy the application?
Yes. Deployment can be discussed depending on the project scope. I can provide a Docker-ready application or help with deployment requirements.