Browse categories
English
$
USD
Connect to your AI


Your documents hold the answers, but finding them takes too long and a generic chatbot will invent one.
I build assistants that answer only from your files and show the exact page, row or URL behind every answer. If the evidence is not in your documents, they say so instead of guessing.
Two levels, one system.
The Document Q&A build (Basic and Standard) is a Python app for a small set of files: PDF, CSV, TXT, Markdown or web pages. It runs on your laptop, shows the sources under every answer, and comes with a setup guide.
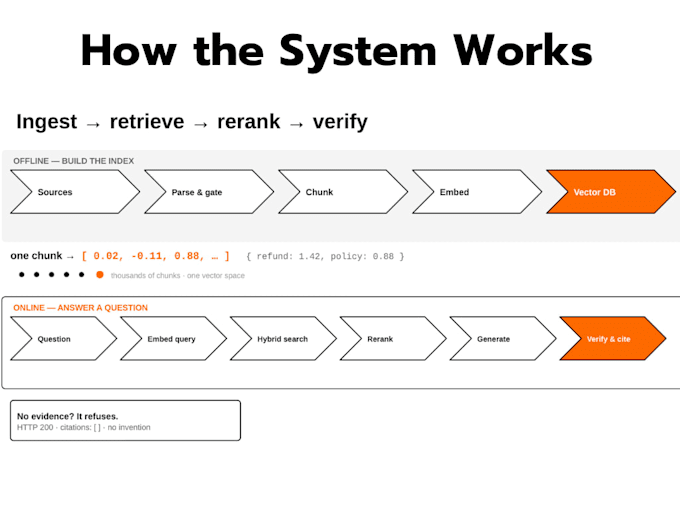
The ResearchOS build (Premium) is for large corpora. Hybrid search that combines meaning with exact terms, an LLM rerank step, sentence-aware chunking, a page quality gate that drops unreadable pages, and citations validated before you see them. It ships as FastAPI + PostgreSQL + Qdrant in Docker on your server, with an evaluation run on your own documents.
I test everything against your sample questions before delivery.
Not included: OCR for scanned PDFs, multi-tenant SaaS, custom model training, legal or medical advice
AI Engineer, RAG, LLM Apps and Automation
Languages
Can it read scanned PDFs?
No OCR. Pages with no text layer return nothing rather than guesses. In the Premium build the quality gate drops them explicitly and reports how many pages were skipped. If your scan is image-only, tell me before ordering , I'll tell you honestly whether it will work.
What's the difference between Standard and Premium?
Standard is a lightweight local app for a handful of files. Premium is a deployable system for a large corpus: hybrid search, reranking, a PostgreSQL + Qdrant backend, Docker, and a measured evaluation report. If you're unsure, send your page count and I'll point you to the right tier.
Will it invent answers?
It's built to refuse. When retrieval finds no evidence, it returns an empty source list instead of generating. In Premium, citation numbers are validated against what was actually retrieved, so fabricated references are removed before you see the answer.
How accurate is it?
I measure it and report it. On a 296-page test corpus: recall@10 1.00, nDCG@10 0.72, citation precision 0.59, and every answer grounded in at least one source. That's a small hand-graded baseline, not a benchmark — and anyone promising 100% citation accuracy is guessing.
Is my data sent anywhere?
Embeddings and answers go to OpenAI or Gemini using your key. Your documents, chunks and vectors stay on your own machine or server — PostgreSQL and Qdrant in Premium run locally.
Do I need a server?
Basic and Standard: no, your laptop. Premium: Docker with PostgreSQL and Qdrant; I include the compose file and deployment notes.