Browse categories
Explore
Fiverr Pro
English
$
USD
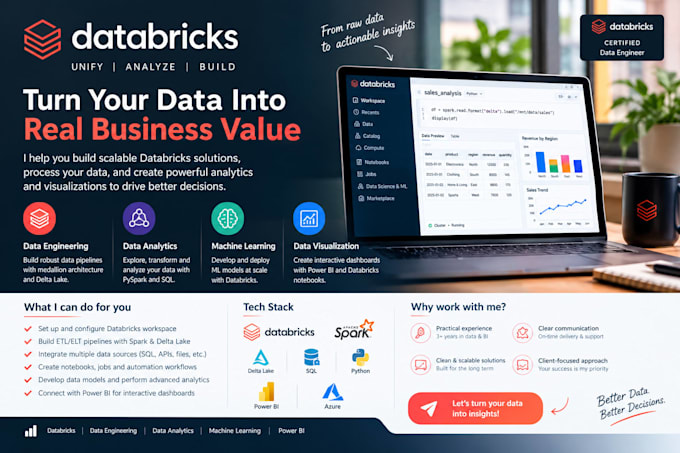
Transform Your Raw Data into Reliable Data Pipelines with Databricks!
Are you looking for help with data processing, ETL pipelines, or big data transformation using Databricks?
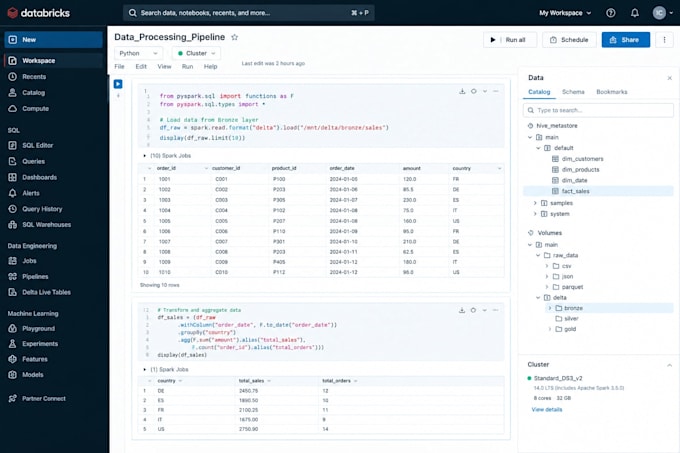
I can help you build, optimize, and maintain data pipelines using Databricks, PySpark, Python, SQL, and Delta Lake, tailored to your project requirements.
With 3+ years of experience in data analytics, ETL development, data transformation, and business intelligence, I understand how to turn raw data into structured, reliable, and analysis-ready datasets.
My Databricks Services
1. Databricks & PySpark Development
2. ETL/ELT Data Pipelines
3. Delta Lake & Lakehouse
4. SQL & Data Optimization
What are your input data sources and formats?
Do you already have a Databricks workspace?
What do you need to start?
Plase provide your project requirements, sample data, expected output, and details about your Databricks environment.