Browse categories
Explore
Fiverr Pro
English
$
USD
Data Scientist building ML, Power BI, Statistics, AI Apps
Messy, duplicated, half-empty data? I'll turn it into clean, reliable, analysis-ready tables.
I'm Muhammad, an MSc-qualified data scientist and data engineer. I clean and structure data so every later step, dashboards, models, reports, rests on something you can trust.
What I do:
Formats: Excel, CSV, JSON, SQL databases and more.
Why me:
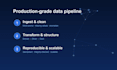
Recent work includes a medallion pipeline that hit 5.3x compression with byte-identical, fully reproducible builds across 11 modeling-ready tables.
Please message me before ordering with a sample of your data so I can confirm scope and the right package.
Technology:
Python
•
R
•
SQL
Should I contact you before ordering?
Yes, send a sample so I can confirm scope and package.
Do I get a reusable script or just cleaned files?
Standard and Premium include documented, re-runnable scripts; Basic delivers the cleaned file plus a log.
Can you handle large or big data?
Yes, I use PySpark and Spark for datasets too big for pandas.
Will the process be reproducible?
Yes, every step is documented so you can re-run it on new data.
Is my data confidential?
Yes, and I can sign an NDA on request.


