Browse categories
Explore
Fiverr Pro
English
$
USD
Senior SRE and Backend Architecture Consultant
Stop flying blind when your backend fails.
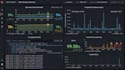
In modern microservices, knowing why a system crashed is often harder than fixing it. Visibility is the foundation of Site Reliability Engineering (SRE). I specialize in engineering enterprise-grade observability stacks that transform chaotic logs into actionable metrics.
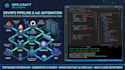
As a Senior Backend Architect, I don't just install tools; I build resilient monitoring architectures.
What this SRE Gig covers:
This is a premium L3 infrastructure service, not basic IT support. Partner with me to bring true SRE culture to your backend.
️ Special Launch Pricing: Please note that these current rates are exclusively for my
What kind of access do you need to complete the setup?
I will need SSH access to your target servers or cluster. For cloud environments (like AWS, GCP), an IAM user with scoped permissions is strictly preferred for your security. If you have strict compliance policies, we can complete the deployment via a guided screen-share session.
Will installing these monitoring agents slow down my servers?
Not at all. I use highly optimized, lightweight agents (like Promtail) designed specifically for enterprise microservices. They run with minimal CPU and memory overhead, ensuring your application's performance remains unaffected.
Can you monitor custom application logs and database queries, or just basic server health?
Both. While basic setups cover infrastructure (CPU, RAM), my advanced packages dive deep into custom backend logs, API timeouts, and heavy database query optimizations (PostgreSQL/MongoDB) using advanced LogQL.
I have a highly complex, multi-cluster architecture. How should we proceed?
Please send me a message before placing an order. Complex enterprise architectures require a custom approach. We will discuss your bottlenecks first, and I will provide a tailored technical roadmap and a custom offer.


