Browse categories
Explore
Fiverr Pro
English
$
USD

Your documents already hold the answers. I build the AI assistant that finds them.
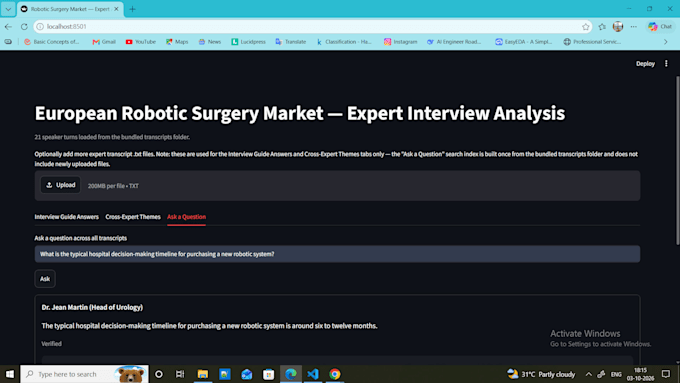
I design custom Retrieval-Augmented Generation (RAG) apps that let you ask questions in plain English and get answers grounded in your own files with the exact source quote behind each one.
Unlike generic chatbots that confidently invent facts, my builds are engineered against hallucination: every answer is retrieved from your documents, validated against a strict schema, and the supporting quote is programmatically checked against the source text. Unverifiable claims get flagged, not faked.
What I build
Q&A chatbots over PDFs, reports, transcripts, contracts or a knowledge base
Structured extraction of defined fields from every document
Cross-document synthesis common themes and disagreements
A clean Streamlit interface your team can actually use
Stack
LangChain, Hugging Face & OpenAI models, FAISS vector search, sentence-transformer embeddings, Pydantic structured outputs, Streamlit, Python.
Reference build
See the portfolio item an expert-interview analyser that returns verified quotes with timestamps from market-research transcripts.
Message me with your documents and the questions you need answe
AI Engineer, LLMs, RAG, MultiAgents Systems, Python, LangGraph, LangChain
Languages
What kinds of documents can you work with?
PDFs, Word files, plain text, transcripts, CSV, and scraped web pages. If you can share a sample, I'll confirm it parses cleanly before you order.
How do you keep the answers accurate?
Every answer is generated only from your documents (retrieval-grounded, not from the model's memory), constrained to a strict data schema, and the supporting quote is checked against the source text before it's shown. If it can't be verified, the app flags it instead of presenting it as fact.
Which AI model do you use?
It depends on your needs. I commonly use Meta Llama 3.1 via Hugging Face, and can use OpenAI or an open local model if you need lower cost or full privacy. We'll pick together on the first message.
Do I get the source code?
Yes — every package includes the full, documented source code and a setup guide. No lock-in.
Can it run privately on my own data?
Yes. For sensitive data we can run a self-hosted open model so nothing leaves your environment.
Can you deploy it for me?
Yes, as a Premium feature or a gig extra. You'll get a working link and the hosting configured.
How much data can it handle?
It scales from a handful of files to thousands of documents. Beyond a small corpus I persist the vector index to disk so it isn't rebuilt on every run.
What do you need from me to start?
Your documents (or a representative sample), 3–5 example questions you want answered, and any branding or interface preferences.
