Browse categories
Explore
Fiverr Pro
English
$
USD
Use the full 1200-character space to make the Gig keyword-rich but still readable:
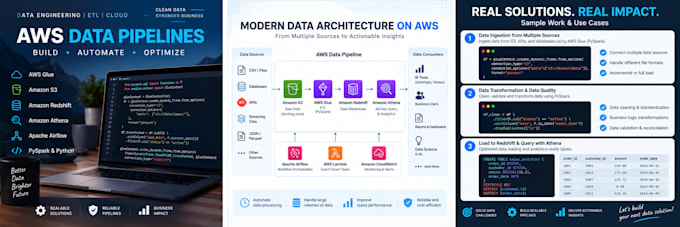
I will build reliable and scalable AWS ETL data pipelines using AWS Glue, PySpark, Python, Amazon S3, Amazon Redshift and other AWS services.
I can help you develop new data pipelines, automate data processing, transform datasets, or troubleshoot existing ETL workflows.
My services include:
AWS Glue ETL job development
PySpark and Python data transformations
S3 data ingestion and processing
CSV, JSON and Parquet data processing
Redshift data loading and transformation
Athena and Apache Iceberg solutions
Data validation and reconciliation
Error handling and pipeline logging
ETL performance optimization
Data migration and automation
I focus on clean, maintainable and production-ready solutions with proper validation, error handling and documentation.
Whether you need a small ETL task or a complete AWS data pipeline, I can develop a solution based on your requirements.
Please contact me before placing an order for complex or multi-service requirements so I can understand your scope and recommend the appropriate package.
Technology:
Amazon Redshift
•
Excel
•
Python
•
SQL
•
NoSQL
•
Apache Airflow