Browse categories
Explore
Fiverr Pro
English
$
USD


Your AI app works in the demo but breaks with real users: wrong answers, hallucinations, slow responses, surprising API bills. I'll find out why and fix it.
Common fixes:
Works with LangChain, LlamaIndex, raw OpenAI/Claude SDKs, Vercel AI SDK, AWS Bedrock and n8n.
Why me: As an Engineering Manager leading AI initiatives, I've shipped production RAG pipelines and AI review agents, and I care about the unglamorous parts: evals, failure cases and cost per request.
Message me with your stack and 3-5 examples of bad outputs.
Engineering Manager building production RAG and AI agents
Languages
Do you need access to my code?
Read access to the repo is best. For the Audit package, code snippets plus a screen share also work.
Will you rewrite everything?
No. I make the smallest change that fixes the problem, and explain why.
How do I know it actually improved?
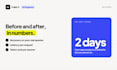
Standard and Premium include before/after numbers on a test set: accuracy, latency and cost per request.


