Browse categories
Explore
Fiverr Pro
English
$
USD

Description:
Shipping an LLM feature without an eval suite is shipping blind. I design and build evaluation pipelines that tell you, with numbers, whether your prompts, model or RAG setup actually got better before your users do.
What you get:
Please reach out to me before placing the error.
LLM AI Model Evaluation Specialist , QA automation Architect ,Eval pipelines
Languages
Do I need to share my production data?
No. I work from samples you choose, synthetic data, or a redacted export. Everything stays under your NDA and is deleted on delivery.
Which eval tools do you use?
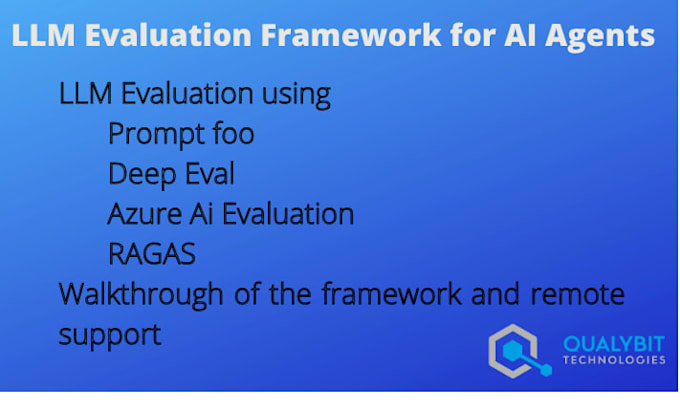
Which eval tools do you use? Promptfoo, LangSmith, Ragas, DeepEval, or a plain Python/pytest harness. I pick what fits your stack; the code is yours either way.
Can you evaluate a RAG system or an agent, not just a single prompt?
Yes. For RAG I score retrieval and generation separately (context precision/recall, faithfulness, answer relevance). For agents I evaluate tool-call correctness and task completion.
What does "LLM-as-judge" mean and is it reliable?
A second model grades outputs against a rubric I write with you. I calibrate it against a human-labelled sample so you know how much to trust the scores.
Do you also do red-teaming or model comparison?
Yes — both are separate gigs on my profile, or add them as extras here.