Browse categories
Explore
Fiverr Pro
English
$
USD
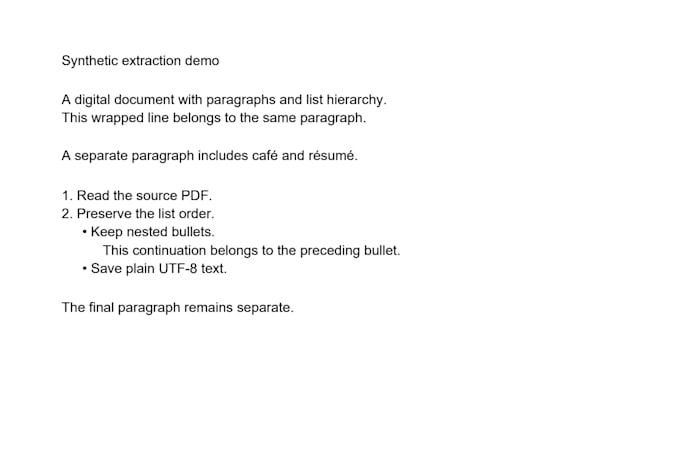
Get clean UTF-8 plain text from digital PDFs, preserving paragraphs and numbered or nested bullet lists.
Basic: 1 PDF, up to 10 pages, 2 days.
Standard: up to 3 PDFs, 30 total pages, 3 days.
Premium: up to 5 PDFs, 50 total pages, 3 days.
Each package includes one .txt file per PDF, a Python extraction script, a usage note and one revision for errors in the original supplied files. Output is checked against your originals.
Files must have selectable text in a single-column layout. Scans/OCR, tables, multiple columns, forms, handwriting, images and visual page-layout reproduction are excluded. Source files are not modified.
This work is AI-assisted using Codex under Rounak's account. Samples are original synthetic demonstrations, not previous client work. The sample passed six checks; accuracy on unseen files is not guaranteed. No paid AI API is needed.
Provide only files you are authorized to share, without passwords or unnecessary sensitive information. If unsure, message with a non-sensitive sample before ordering.

Convert from:
Convert to:
Other
Can you process scans or tables?
This package covers selectable text in single-column digital PDFs. Scans, OCR, tables, forms and multiple columns are outside its scope. Send a non-sensitive representative sample before ordering if unsure.
Will the text look exactly like the PDF?
The output is plain text. Paragraph breaks and supported lists are preserved, but fonts, images, tables and visual page design are excluded.
What does one revision cover?
Correction of extraction mistakes in the original supplied files. New documents, OCR or a different output format require a separately agreed scope.
Are the samples from previous clients?
No. They are original synthetic demonstrations, not paid client work. This service uses disclosed AI assistance under Rounak's account.