Browse categories
Explore
Fiverr Pro
English
$
USD


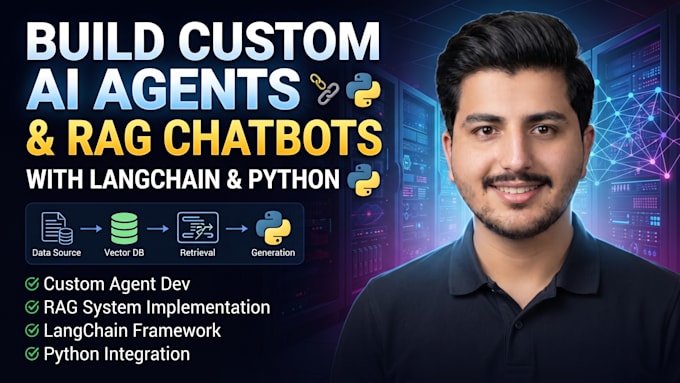
Looking for AI agents that survive real users, not demos that hallucinate or crash under load? I build custom AI agents and RAG chatbots with LangChain, LangGraph, and Python engineered for production from day one.
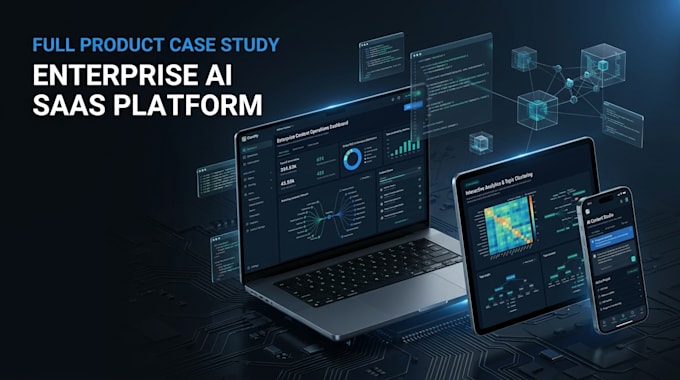
I'm Muhammad Rovaid, full-stack AI engineer. Built Contlify, an AI-native content automation engine. I specialize in RAG pipelines, multi-agent systems, and high-concurrency backends.
WHAT YOU GET:
RAG chatbots answering from YOUR documents pgvector, Pinecone, ChromaDB, Qdrant, semantic reranking, citation checks. Zero hallucination. Great for document Q&A, support bots, knowledge bases.
AI agents with LangChain/LangGraph Pydantic/Zod schemas, tool calling, multi-agent workflows. Works with OpenAI GPT, Claude, and Gemini.
Scalable Python backends async FastAPI with Redis queues, no timeouts under load.
Full-stack AI SaaS Next.js 15, Supabase Auth, Stripe billing, Docker/Vercel deploys.
PROCESS: Free architecture plan clean build you test, I revise deploy + handover, you own 100% IP.
WHY ME: Semantic caching cuts token costs up to 40%. Guardrails stop false answers.
Message me for a free architecture plan - or order now and let's kick off!
Production Ready AI Agents, Custom RAG and Full Stack Web App
Languages
How do you prevent the AI agent from hallucinating or going off-topic?
I implement three distinct guardrails: strict system constraints, semantic reranking of vector context, and deterministic schema enforcement using Pydantic/Zod. If knowledge retrieval confidence is below a safe threshold, the agent safely falls back to a verified response rather than guessing.
What tech stack do you recommend for my project?
For the AI orchestration and backend logic, I use Python (FastAPI/LangChain) with Supabase (PostgreSQL + pgvector). For the frontend, I build in Next.js 15 with Tailwind CSS. This stack guarantees rapid edge performance, seamless authentication, and low hosting costs.
Can this backend handle hundreds or thousands of simultaneous users?
Yes. Unlike beginner implementations that use blocking synchronous calls, I design asynchronous endpoints backed by background worker queues (Redis) and caching. This ensures your server never times out or drops a request under sudden traffic spikes.
Will I own the code, and how will it be deployed?
You receive 100% intellectual property rights and full source code. I provide automated deployment configurations (Docker, Vercel, Railway, or AWS) along with complete setup documentation so your team can maintain it effortlessly.
Can you build a RAG chatbot that answers questions from my PDFs and documents?
Yes — that's my core service. I load your PDFs and docs into a pgvector or Pinecone vector database with semantic reranking and citation checks, so every answer is grounded in your data with zero hallucination.
Which AI models do you work with — OpenAI, Claude, or open-source models?
All of them. I recommend the best model for your use case and budget — OpenAI and Claude for top quality, or open-source models via Ollama when data privacy or cost matters.
Can you integrate the AI agent with my website, WhatsApp, or existing API?
Yes. I ship every system with a REST API, so it connects to websites, WhatsApp, CRMs, or any platform via webhooks and API integrations.
How do you prevent the chatbot from hallucinating wrong answers?
Three layers: answers are grounded in your documents via RAG, reranked semantically, and citation-checked. Anything ungrounded gets blocked instead of invented.
Will I own the code, and how do you deploy it?
You own 100% of the IP with clean, documented code. I deploy with Docker or Vercel and hand over everything you need to run it yourself.