Browse categories
English
$
USD
Connect to your AI
Database architecture and Python bug fixing
I turn scanned PDFs, invoices, statements and forms into one clean spreadsheet you can actually use.
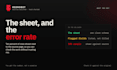
What you get: one file, one schema, every field in its own column. Low-confidence fields flagged, not guessed. Plus a verification sample, 10% of rows shown next to the source page, so you can check the work yourself.
How it runs: machine-assisted and hand-checked. Extraction runs first, then I go through every flagged field by hand and spot-check against the originals. You get the error rate stated rather than hidden.
Standard adds normalisation: dates, currencies and names made consistent across the whole set. Premium adds a second pass on every flagged field, plus the extraction rules written down.
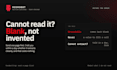
I do not type anything I cannot read. Illegible fields come back flagged and blank. I never invent a value to fill a cell, and I do not deliver without the sample.
Handwriting is not included unless you send a page first and I confirm it reads.
Unsure? Send one sample page before ordering. I tell you within a day whether it extracts cleanly, and that costs nothing.
Handwritten documents?
Send one page first. Printed handwriting often works, cursive usually does not. I tell you before you pay.
Is this AI?
Yes. Machine-assisted, hand-checked, and the verification sample ships with it. I state it rather than hide it.
What if the layout changes mid-document?
Normal. Tell me the variants you know about and I handle the rest.
Which output formats?
XLSX, CSV, or Google Sheets. Tell me which and I match your existing column names if you have them.
Sensitive documents?
Redact what I do not need before sending. I only need the fields being extracted, not the rest of the page.