Browse categories
English
$
USD
Connect to your AI
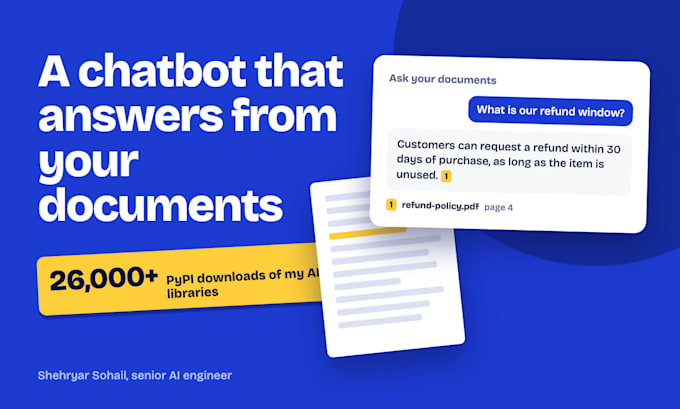
I build document chatbots that answer only from your files and show where each answer came from.
Relevant work: I built SkyLocker, a WhatsApp assistant that stores, searches and returns users' files using multimodal RAG over text and images (Milvus, ChromaDB, OpenAI, S3). I also maintain ocr-llm, an open-source library that turns messy and scanned PDFs into clean Markdown using vision LLMs (3,000+ PyPI downloads), which matters because bad PDF parsing is where most document chatbots quietly fail.
What you get: your PDFs and text files parsed, chunked and indexed; a chatbot that retrieves the right passages and answers only from them; a citation on every answer; and an honest 'I don't know' when your documents don't cover the question. It can live on your website, WhatsApp or Slack.
How I work: we agree the documents and the questions it must handle, I build it, then I test it on real questions from your documents before handover.
Stack: OpenAI or Claude, Python, FastAPI, vector databases (pgvector, Pinecone, Milvus), Next.js widget.
Message me before ordering with your documents and use case, and I will tell you which package fits.
AI engineer: voice agents, LLM apps, RAG and document extraction
Languages
Can it read scanned PDFs?
Yes, from the Standard package up. I use vision LLMs to turn scanned pages into clean text first, the same approach as my open-source ocr-llm library.
What happens when the answer is not in my documents?
It says it doesn't know instead of guessing. Answers only come from your content, and each one shows the document and passage it used.
