Browse categories
Explore
Fiverr Pro
English
$
USD
Most "AI chatbots" on the market are a thin wrapper around ChatGPT that hallucinate answers and have no idea what's actually in your documents. That's not what I build.
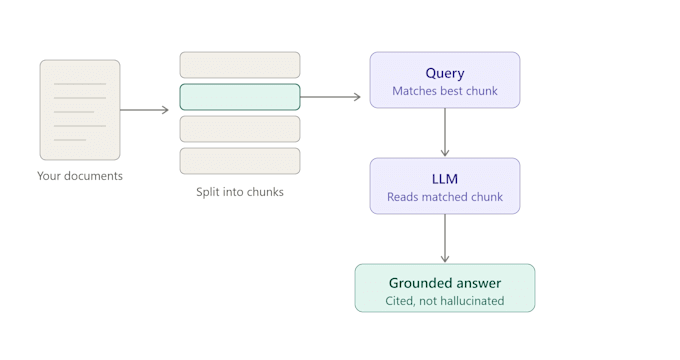
I'm an ML engineer who builds production-grade RAG (Retrieval-Augmented Generation) systems chatbots and assistants that actually ground their answers in your data: PDFs, docs, websites, knowledge bases, support tickets, product catalogs, whatever you've got.
What makes my RAG builds different:
What you get:
Programming language:
Python
•
SQL
Frameworks:
Scikit-learn
•
Keras
•
PyTorch
•
Panda
APIs:
Other
Tools:
Jupyter Notebook
•
Excel
Do I need to provide my own OpenAI/Anthropic API key?
Yes, you'll need your own API key for the LLM provider, this keeps your usage costs transparent and directly billed to you, not marked up by me.
What data formats can you work with?
PDFs, Word docs, plain text, websites (via scraping), CSVs, and structured knowledge bases. Let me know your format before ordering if unsure.
Can this integrate with my existing website/app?
Yes — Standard and Premium tiers include integration-ready delivery (API or web interface). Basic tier delivers a standalone script.
How is this different from just using ChatGPT directly?
ChatGPT alone doesn't know your specific data and will hallucinate answers. A RAG system retrieves the actual relevant content from your documents before generating a response, so answers are grounded in what you actually provided — not the model's general training data.
What if my project doesn't fit these packages?
Message me first, happy to scope a custom package for larger or unusual requirements.
