Browse categories
Explore
Fiverr Pro
English
$
USD
Python scraping, data automation, Chinese sites specialist
Need a tool that turns PDFs, scanned documents, images or pasted text into clean, structured data? I build custom AI data extraction software (Python, FastAPI, React) around your documents and your fields.
WHAT YOU GET
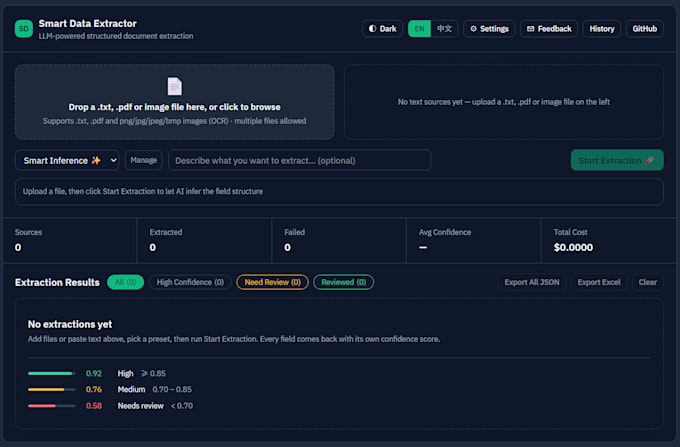
- An extraction pipeline using an LLM and OCR, built to your schema (invoices, business cards, leads, forms, or anything else)
- Format validation for email, phone, URL and date fields
- A confidence score on every field. Missing values are left empty and flagged, never invented
- JSON/Excel export, delivered as a CLI, REST API or web app depending on your package
- Source code, automated tests and a README
WHY THIS APPROACH
Many LLM extraction demos look fine until they quietly invent a value. I design against that: validation, confidence signals from the OCR engine, and a review screen for uncertain fields. I don't promise 100% accuracy, but wrong or missing fields get flagged instead of slipping through.
This gig is based on a working project of mine with over 700 automated tests. English and Chinese documents are supported.
BEFORE YOU ORDER
Message me with 3-5 sample documents and the fields you need, so I can confirm the scope and the right package.
Technology:
Python
Expertise:
API integration
•
Data extraction
•
Data validation
