Browse categories
Explore
Fiverr Pro
English
$
USD

LLM apps without a gateway and traces turn into guesswork: no idea which key spent what, which model is slow, or why costs doubled after launch. I set up LiteLLM + Langfuse so you can see and control all of it.
WHAT I SET UP
- LiteLLM proxy on Docker, VPS or your cloud, with an OpenAI-compatible /v1 endpoint
- Multi-provider routing: OpenAI, Anthropic, Gemini, Azure, Bedrock, OpenRouter, local models
- Virtual keys per app/team with budgets, RPM/TPM limits and per-model access
- Fallback chains and automatic retry/failover on 429, 500 and timeouts
- Cost tracking per key, per model, per customer, with 60/80/100% spend alerts
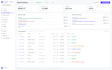
- Langfuse (or LangSmith/Helicone) traces, latency percentiles and error logs
- One dashboard or weekly report your team can actually read
- config.yaml, deployment notes and a handoff runbook
This is not a chatbot build. It's for teams already running or shipping an LLM app who want production control over it.
Send your providers, traffic estimate and where it runs today. I'll confirm scope in 24h.
AI LLM Engineer RAG, Agents, LLM Ops Shopify Hydrogen
Languages
LiteLLM, OpenRouter or Portkey — which do I need
OpenRouter if you want managed access to many models with minimal infra and accept per-token markup. LiteLLM self-hosted if you need your own keys, budgets, data locality or zero per-request markup. I'll recommend whichever fits, including "keep what you have".
Will my app code need rewriting?
Almost never. LiteLLM exposes an OpenAI-compatible endpoint, so it's usually a base-URL and key change. I refactor only where retries or streaming need attention, and I show you the diff.
Does this track cost per customer?
Yes — that's the main reason teams buy it. Per-virtual-key and per-tag spend, so you can see which customer or feature is unprofitable. I model your pricing math on request as an add-on.
Self-hosted or Langfuse Cloud?
Both work. Cloud is fastest and I'll set it up same-day; self-hosted keeps traces and prompt text inside your VPC, which matters if you handle regulated data. Tell me your constraint and I'll pick.
Can you migrate keys without downtime?
Yes. I run the gateway in shadow mode beside your direct calls, verify identical outputs and costs, then cut over. Rollback is one env var, so a bad deploy isn't an incident.


