I will deploy and tune a private self hosted llm on your own GPU server

S
stchopko
S
stchopko
Stepan C.

About this gig

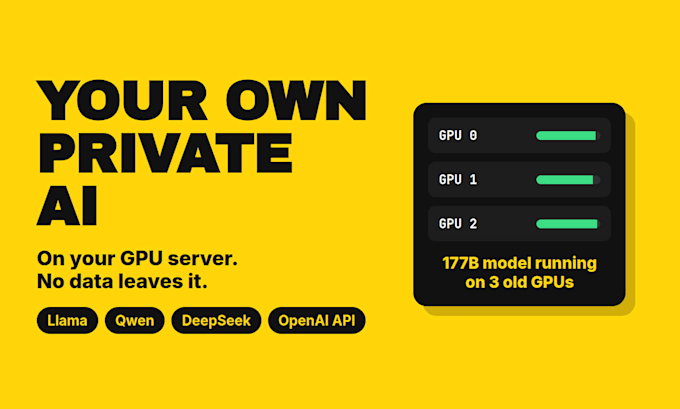
Want ChatGPT-style AI that runs on your own hardware, with zero data sent to third parties? I'll set it up and make it fast.


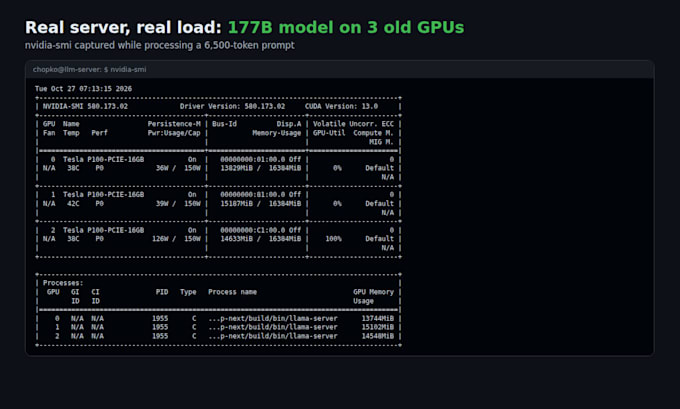
Most setups just install a runner with default settings and leave 2-3x performance on the table. I benchmark and tune for your exact GPU and RAM. Real results from my own server (Tesla V100 + P100, AMD EPYC):

  • 35B MoE model at 1,070 tokens/s prompt processing and 69 tokens/s generation (23k context)
  • 3.4x faster prompt processing (75 to 254 tokens/s) by tuning batch sizes
  • 177B MoE model on just two 16GB GPUs at 14 tokens/s
  • The right quantization for your GPU generation

What you get:

  • llama.cpp server with an OpenAI-compatible API
  • Web chat interface
  • Model selection for your hardware and use case
  • Auto-start service and secure remote access
  • Benchmark report: what speed you get and why

Send me your GPU, RAM and what you want the AI to do, and I'll tell you what's realistic before you order.

Get to know Stepan C.

Stepan C.

PHP Developer and Self Hosted LLM Engineer

  • FromUkraine
  • Member sinceMay 2021
  • Languages

    Ukrainian, English
Backend developer with 9 years of commercial PHP (Symfony, Laravel, legacy code), including 6 years as Senior PHP Developer at an Irish software company, and hands-on experience running large language models on my own hardware. I fix and upgrade PHP sites that broke after a PHP 8.x update, migrate projects to modern Linux servers, and deploy private, self-hosted LLMs that run on your own GPU - no data leaves your server. I don't guess: I find the root cause, fix it, and tell you what was wrong. Clear written communication, fast replies.