Browse categories
Explore
Fiverr Pro
English
$
USD

Stop relying on AI chatbots that hallucinate. To get real business value from Large Language Models, they need to understand YOUR data.
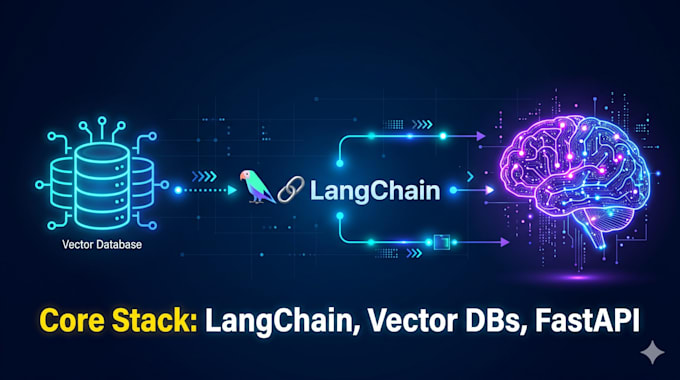
I engineer custom, production-grade AI agents and Retrieval-Augmented Generation (RAG) pipelines that securely integrate with your proprietary enterprise knowledge base.
As a Principal AI/ML Engineer, I specialize in moving AI from experimental notebooks into highly scalable software applications. In past commercial deployments, my custom LLM architectures boosted user engagement by 40%.
What I Build:
Stack: Python, LangChain, OpenAI, FastAPI, Vector DBs, AWS.
Message me with your project goals, and let's get started!
Generative AI, RAG, and Edge Computing Expert
Languages
Is my proprietary data secure? Will it be used to train public models?
Yes, your data is completely secure. I build RAG pipelines using enterprise-tier APIs and dedicated Vector Databases. Your documents are used strictly for context retrieval and are never used to train base models like OpenAI's public GPT.
How is this different from just using standard ChatGPT?
Standard LLMs often hallucinate facts and have no knowledge of your internal business operations. A custom RAG pipeline restricts the AI to only pull answers from the specific documents or databases you provide, ensuring highly accurate and factual responses.
What types of data or documents can the AI agent process?
I can integrate a wide variety of data sources, including PDFs, CSV/Excel files, SQL databases, Word documents, and internal wikis like Notion or Confluence.
What technology stack do you use to build the backend?
I architect these systems using Python, LangChain, and LangGraph for the AI workflows. For the backend infrastructure, I use FastAPI and Redis to ensure the application can handle high traffic (30+ RPS) with low latency, containerized with Docker.
Do you help with deploying the agent to the cloud?
Yes. If you select the Premium Enterprise package, I provide a fully containerized Docker setup and deployment configuration. It will be completely ready to host on your preferred cloud provider, such as AWS, GCP, or Azure.