Browse categories
Explore
Fiverr Pro
English
$
USD
Python Developer, Web Scraping, Data Automation
Custom AI-Powered Data Extraction for PDFs & Images
Turn your PDFs, scanned documents, and images into structured data with a custom AI-powered extraction application.
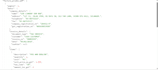
I configure the software for your specific document types and fields, so you can extract information and export it to Excel, CSV, or JSON.
What you get:
Send me your document sample and the fields you need to extract, and Ill configure the solution for your requirements.

Do I need coding skills to use the application?
No coding skills needed. The app runs locally for 100% data privacy. You only need Python installed to launch it, and I include a step-by-step PDF guide showing you how to do it in minutes. Once opened, you just use the simple interface.
What happens if I have document layouts not included in my package?
If you select the Premium package, you get access to the Free Prompt Mode, which allows you to extract raw JSON data from unconfigured document formats on the fly.
How does the API key configuration work?
The application connects directly using your own API key to ensure full ownership and control over your data limits. If needed, I can provide a temporary key for initial testing.
How does the app handle multi-page or fragmented invoices?
The app includes a visual PDF merging tool. You can adjust crop sliders to remove unwanted headers or footers and combine the exact sections from different pages into a clean, single PDF for optimal extraction.


