Browse categories
Explore
Fiverr Pro
English
$
USD
Clean Sourced Verified: Data Entry, Excel, Lead Lists
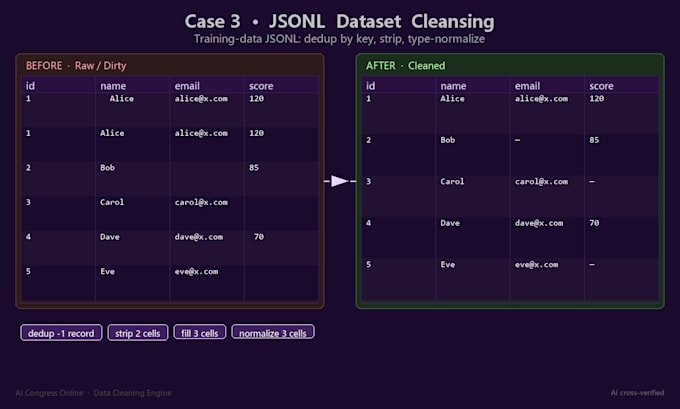
Are you building an LLM, RAG system, or fine-tuning project, but your training data is a mess? Duplicate rows, inconsistent field names, empty values, malformed JSON these don't just slow down training, they silently degrade your model's output quality.
I clean and prepare training datasets so they're ready to feed directly into your pipeline. My pipeline handles JSONL, CSV, XLSX, and even messy exports from Notion, Excel, or scraped sources. Every cleaning operation is logged you get a report showing exactly what was changed, nothing hidden.
Here's what makes this different:
Multi-model AI cross-verification on Standard/Premium two AI models review the cleaned data independently, and discrepancies are flagged for you
Schema preservation I clean the data, I never touch your field names or structure
Operation audit trail every dedup, every normalization, every removed bad row is documented
What you get:
1. Cleaned dataset in your requested format
2. A cleaning report showing what was done
3. Free 1-round revision
Send me a sample of your data first if you're unsure I'll tell you exactly what needs cleaning before you order.
What file formats do you accept?
JSONL, CSV, XLSX, and JSON. If you have something else, send a sample and I'll tell you.
Will you change my data schema or field names?
No. I clean the values, not the structure. Your field names, order, and schema stay exactly as they are.
What does "AI cross-verification" mean?
On Standard and Premium tiers, two independent AI models review the cleaned data and flag any discrepancies. You get a report of what they agreed on and what was uncertain.
How fast can you deliver?
Basic (5K rows) in 3 days, Standard (20K rows) in 5 days, Premium (100K rows) in 7 days. Rush delivery available on request.
What if my data is in a foreign language?
The cleaning pipeline is language-agnostic. It handles Chinese, Japanese, English, or mixed-language datasets.