Browse categories
Explore
Fiverr Pro
English
$
USD
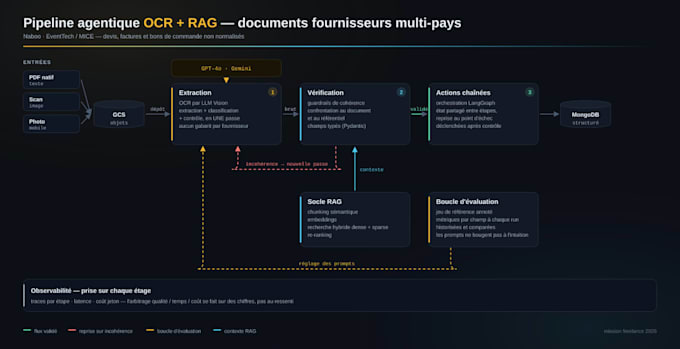
Most RAG demos fail in production because the retrieval is wrong, not the model. I build the retrieval right: semantic chunking, embeddings, hybrid dense+sparse search, re-ranking - and I measure it with an evaluation set, so every change is a number, not an impression.
What you get: a chatbot that answers from YOUR documents, cites its sources, and says "I don't know" when it should. Delivered as an API (FastAPI) with a web chat, Dockerized, with traces and cost per query.
Stack: Python, LangChain/LangGraph, Qdrant or Elasticsearch, OpenAI/Gemini/Mistral or open models on your infrastructure.
Recent work: production RAG engine for two retail brands (Mulliez group), OCR+RAG pipeline for an EventTech startup, document anti-fraud engine for a bank.
Senior AI Engineer, 6+ years, based in France. I lead teams of 2 to 5 engineers.
Senior AI Engineer
Languages
Which LLM do you use?
Your choice: OpenAI, Gemini, Mistral, or an open model hosted on your side for confidentiality. I recommend one based on your documents and budget.
My documents are scanned PDFs. Is that a problem?
No. LLM-vision OCR is part of the pipeline: scans, photos and non-standard layouts are handled.
Where does the chatbot run?
In Docker on your server or your cloud (GCP, Azure, AWS). Nothing stays on my side after delivery.
How do I know it works?
You get an evaluation set: your questions, the expected answers, and a score per version. Every change is measured, not guessed.