Browse categories
English
$
USD
Connect to your AI

Data Scientist
Skills
See my services
Data Scientist
London Stock Exchange Group • Full-time
Sep 2023 - Mar 2026 • 2 yrs 6 mos
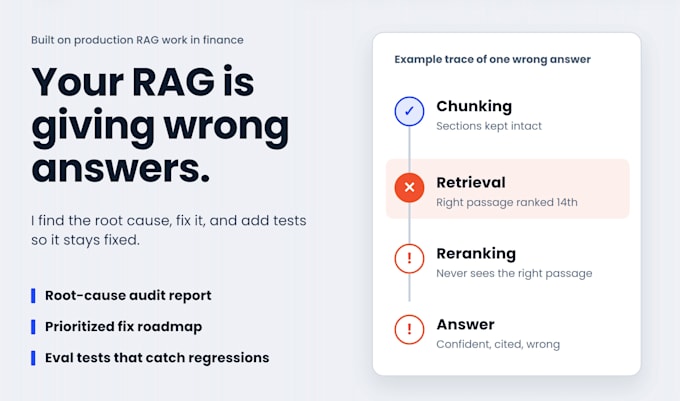
I help teams make LLM and Retrieval-Augmented Generation (RAG) systems reliable, measurable, and production-ready. I’ve built and improved GPT-based RAG pipelines for unstructured financial data, using evaluation-driven iteration and retrieval optimization to improve answer quality. I can choose the right tools and strategies for your specific data (PDF/web/docs, noisy or domain-specific content) and help you customize the pipeline end-to-end: document parsing, chunking strategy, embeddings & vector retrieval, metadata filtering, reranking, and prompt/citation tuning. If your RAG system hallucinates, misses key facts, or retrieves irrelevant context, I’ll diagnose the root causes and deliver a clear plan to improve answer quality. My deliverables are practical and verifiable: an audit report with evidence-backed findings, a prioritized improvement roadmap (quick wins → longer-term), a failure-case set, and an evaluation blueprint (LLM-as-judge rubric + regression tests) so quality doesn’t regress over time. Strong engineering background: Python, Linux, Git/GitLab CI/CD, and Azure/AWS for scalable evaluation, deployment, and testing. I also publish 40+ technical articles on RAG and LLM engineering (chunking, retrieval, evaluation, JSON reliability), and I use the same frameworks to provide clear documentation and reusable checklists.
