Browse categories
Explore
Fiverr Pro
English
$
USD

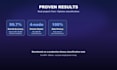

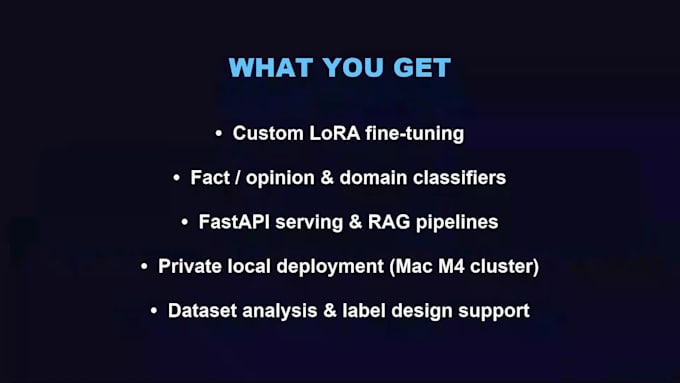
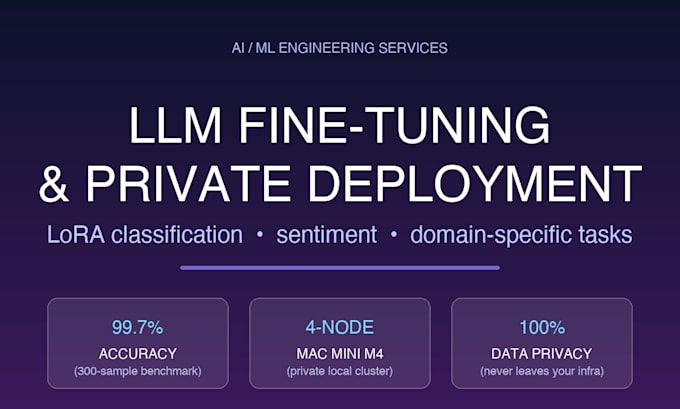
Custom LLM fine-tuning with LoRA/QLoRA for classification, sentiment, style transfer, and domain-specific tasks. I built a fact/opinion binary classifier with Qwen3-14B-4bit LoRA that reached 99.7% accuracy, and I deploy everything on my private 4-node Mac Mini M4 cluster your data never leaves your environment.
What I offer:
Why choose me:
Before ordering: message me with your task, dataset size and format, target language, and deadline so I can confirm feasibility and delivery time.
AI ML Engineer, LLM Fine tuning and Private Deployment Specialist
Languages
What data do you need from me?
Labeled or unlabeled samples in CSV/JSON, or a task description.
Will my data stay private?
Yes, all work runs on my private local cluster, data never leaves your infrastructure.
What do I get after delivery?
Fine-tuned model weights, evaluation report, and deployment guide/API if applicable.
Which models do you fine-tune?
Popular open-source models such as Qwen, Llama, Mistral, and more, using efficient LoRA/QLoRA.
How long will it take?
Typical small to medium tasks are delivered in 3-7 days, depending on data volume and cluster load.
Can you handle non-English text data?
Yes, I can fine-tune multilingual models such as Qwen, BLOOM, or multilingual MiniLM for non-English classification and NLP tasks. Share your language and domain and I will set up the right model for you.
What deployment options do you offer?
Private deployment via FastAPI + Docker (or MLX/vLLM for production throughput) on your own machines - Mac Mini, Linux, or Windows servers. I also set up an internal API endpoint for your team.
What accuracy can I expect?
It depends on data quality and task difficulty. As a reference, my fact/opinion classifier with Qwen3-14B LoRA reached 99.7% accuracy. You always receive a full evaluation report with accuracy, F1, and error analysis.
Why use LoRA/QLoRA instead of full fine-tuning?
LoRA/QLoRA updates only a small fraction of parameters, cutting training cost and memory by up to 90% while keeping quality close to full fine-tuning. It trains faster and produces smaller artifacts, which makes private deployment on modest hardware practical.