 September 30, 2026
 15 minute reading
Most support teams do not break because the people are bad at their jobs. They break because volume grew faster than the operating system around them: no documented process, four channels feeding four separate inboxes, and one person who happens to know how refunds work. A flexible customer care team is one where coverage, quality, and cost can each be adjusted without rebuilding the whole function, and where you can find customer care specialists on Fiverr to fill a specific gap in days rather than quarters.
This guide covers the operational layer: the standard operating procedures and macros that keep answers consistent, the routing rules that keep multi-channel support from leaking tickets, the KPIs worth reviewing weekly, and the staffing models that get you from business hours to extended or 24/7 coverage.
It is written for e-commerce store managers and startup support leads who are past the founder-answering-emails stage and heading toward a real team.
All figures in this guide are based on completed Fiverr orders in Customer Service, AI Chatbot Development and Rule Based Chatbots, over the 12 months to August 2026.
At a glance: building a flexible customer care team
- Document your SOPs and macro library before you hire or automate, so new reps and any AI assistance work from one approved standard.
- Consolidate every channel into one queue with one set of routing rules, then set response targets per channel rather than one blended target.
- Track three KPIs to start: CSAT, first response time, and resolution rate. Adding more before those three are clean makes the picture worse, not better.
- Match the coverage model to where demand actually falls. Extended hours, weekend-only cover, and follow-the-sun handoffs each solve a different problem.
- Fiverr provides access to customer care specialists across time zones, and demand for this work is growing fast: completed orders for customer support grew roughly 150% year over year, with median order value holding flat.
What makes a customer care team flexible
A flexible customer care team is one where coverage hours, headcount, and skill mix can change without disrupting service quality. Rigid teams have all three variables locked together, so any change to one forces a hiring cycle or a reorganization.
Flexibility comes from three things being separated. The process lives in documentation rather than in people's heads. The queue lives in one system rather than in individual inboxes. And the staffing is layered, with a small permanent core holding institutional knowledge and a flexible layer absorbing volume swings, launches, and after-hours coverage.
That separation is what lets you answer a Black Friday spike or a product launch without either burning out the core team or over-hiring for a peak that lasts eleven days.
How e-Commerce and SaaS support differ
The two use cases share tooling but not contact drivers, and the difference shapes how you staff.
E-commerce support is high-volume, short-duration, and heavily weighted toward order status, shipping exceptions, returns, and sizing or fit questions. Most tickets are resolvable by policy and a lookup, which means a well-built macro library can carry a large share of the queue. Volume is seasonal and spiky.
SaaS support is lower-volume, longer-duration, and more technical. Tickets involve configuration, integrations, billing logic, and bugs that need engineering escalation. Resolution often takes multiple exchanges, so first-contact resolution is a weaker target than in retail, and a clear tier-two escalation path matters more than raw speed.
Both benefit from the same structure. The tuning is different: e-commerce optimizes for throughput and deflection, SaaS optimizes for accuracy and escalation quality.
Support team structure models
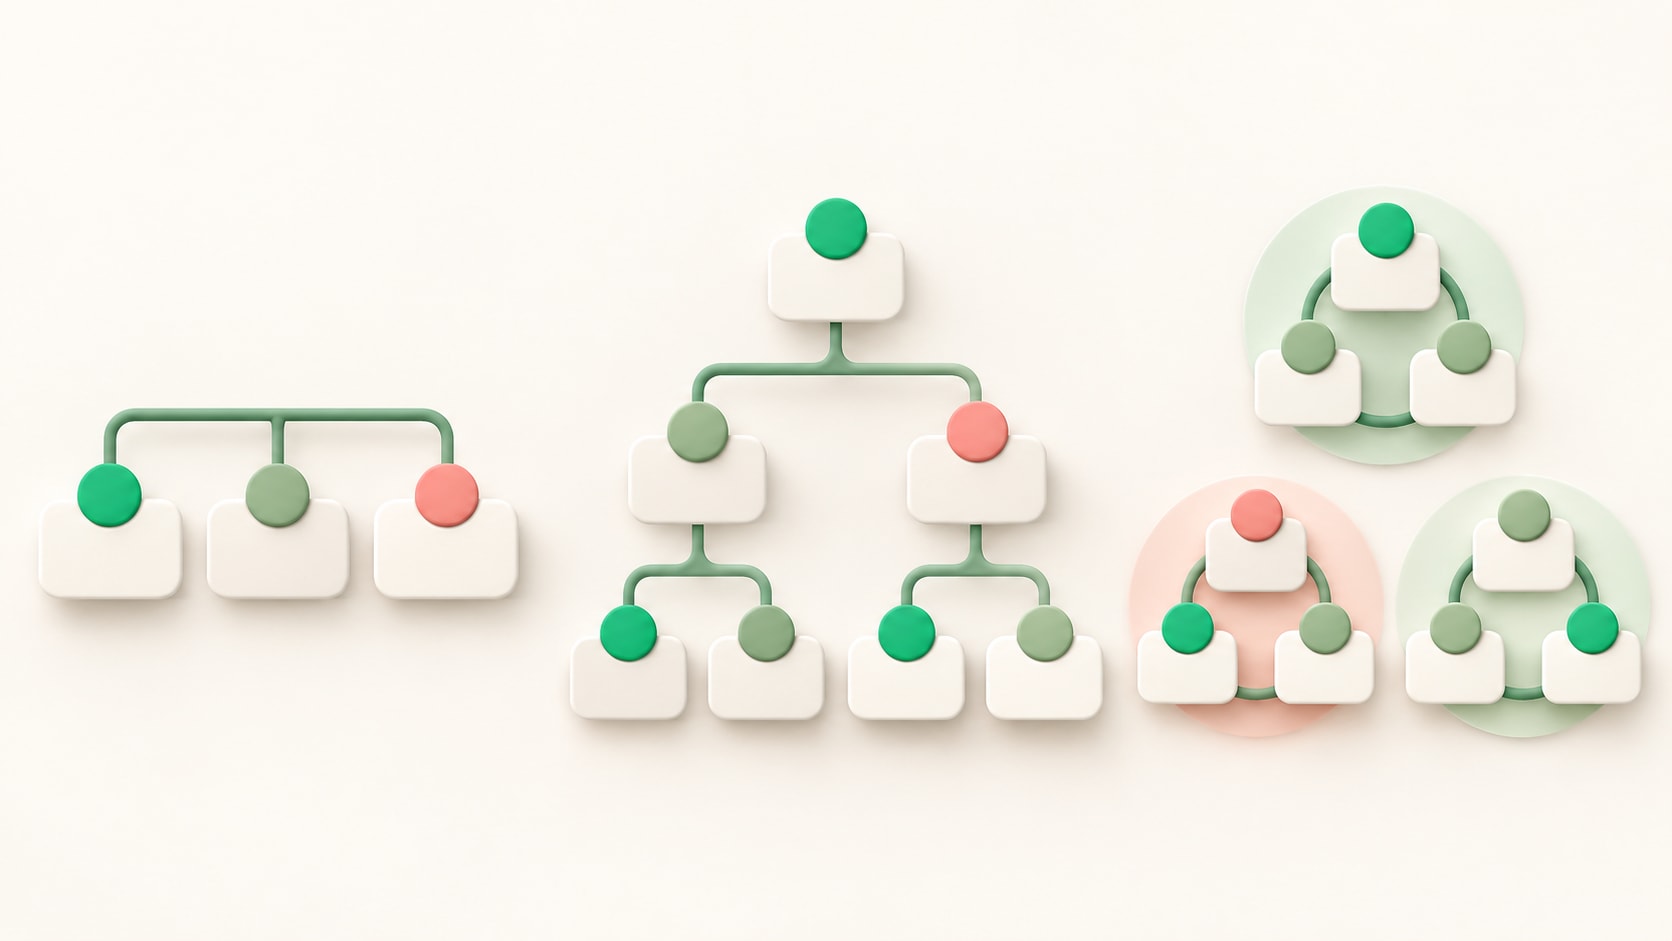
Four structures cover most teams at this stage.
- Flat generalist team. Every rep handles every channel and issue type. Works up to roughly two or three reps and low complexity. Simple, but it caps quality once product complexity grows.
- Tiered team. Tier one handles routine contacts against SOPs and macros. Tier two handles complex, technical, or high-value cases. This is the most common structure once daily volume gets past what two people can absorb.
- Channel-specialized team. Reps own a channel, usually chat versus email and ticketing. Suits teams where live chat volume is high enough to need dedicated real-time staffing.
- Pod structure. Small cross-functional groups each own a customer segment or region. Useful for SaaS teams with named accounts and for follow-the-sun coverage, where each regional pod is self-sufficient.
Most e-commerce and SaaS teams end up tiered, with channel specialization layered on top once chat becomes a meaningful share of contacts.
Before you start: what to have in place
Building the team before these exist produces a team that spends its first month inventing policy under pressure.
- 90 days of ticket data, broken down by volume per day, hour of day, day of week, and contact reason. Without it, every staffing decision is a guess.
- A single helpdesk or ticketing platform, with every channel routed into it. Shared inboxes that live outside the tool will not appear in any report you run.
- Written policies for the decisions reps cannot make alone: refund thresholds, replacement rules, discount authority, escalation triggers, and what customer data each role is allowed to see.
- Current product documentation or a knowledge base, even a rough one. It is the source material for both macros and rep onboarding.
- A defined escalation path, naming who handles tier-two issues and who is reachable outside business hours.
How to build a customer care team in five steps
The sequence matters. Teams that hire first and document later spend the next six months trying to standardize behavior that has already set.
Step 1: Map your volume and contact drivers
Pull the last 90 days of contacts and group them by reason. Most teams find that five to eight contact reasons account for the large majority of volume, which tells you exactly what to write macros for first.
Then plot volume by hour and by weekday. The shape of that curve, not a general belief that customers expect 24/7 service, is what should drive your coverage decision. A store whose contacts cluster between 9am and 9pm local time does not need overnight staffing yet.
Step 2: Set your channel mix and response targets
Decide which channels you will actually staff, then publish a target per channel. Offering live chat you cannot answer inside a few minutes does more damage than not offering it.
Set targets you can hit consistently rather than aspirational ones. A promise of one-hour email replies that you meet 60% of the time reads worse to customers than a four-hour promise you meet 95% of the time.
Step 3: Document SOPs and build the macro library
Write the procedures before the first hire starts. Every contact reason from step one needs a documented handling path and, where the reply is repeatable, a macro.
This is the single highest-leverage step for flexibility. A documented process is what makes a new specialist productive in days, and it is the difference between adding weekend coverage and rewriting your quality standard every time someone new joins.
Step 4: Design coverage windows and staff to them
Take the demand curve from step one and draw coverage blocks over it. Identify the hours that need live staffing, the hours that need monitored-but-async handling, and the hours where an autoresponder with a clear next-reply time is sufficient.
Staff each block separately. This is where flexible staffing does the most work, since evening, weekend, and overnight blocks rarely justify full-time internal roles at this stage.
Step 5: Instrument KPIs and run a weekly review
Turn on CSAT collection, confirm your first response time and resolution rate are being measured against the right clocks, and set a standing weekly review.
The review needs to look at the metrics and a sample of actual conversations together. Metrics alone will tell you the team is fast. Only reading tickets will tell you whether the answers were any good.
How to write SOPs and macros support reps will actually use
An SOP is the decision path for a contact reason. A macro is the pre-written text used at a point in that path. Teams that conflate the two end up with a macro library nobody trusts, because the macros carry policy that changed three months ago.
What belongs in a support SOP
Each SOP should cover one contact reason and stay short enough to read during a live conversation. A workable format:
- Trigger. What the customer said or did that puts the ticket in this category.
- Verification. What the rep confirms first, such as order number, account ownership, or plan tier.
- Decision rules. The if-then logic, including the thresholds where the rep can act alone.
- Resolution actions. The exact steps in each system, in order.
- Escalation trigger. The specific conditions that send it to tier two, and to whom.
- Closing standard. What gets logged, tagged, and confirmed back to the customer.
Write them for the person joining next month, not for the person who already knows. If a step assumes context, the SOP will fail its actual purpose.
How to build a macro library that holds up
Start with the top contact reasons and write one macro per resolution path, not one per situation. Libraries fail by growing to 300 entries that nobody can search, at which point reps go back to typing from scratch.
Practical rules that keep a library usable:
- Name macros by the customer's problem, not by internal jargon. Reps search using the words the customer used.
- Build them as skeletons with variable slots for the specific detail, so every reply requires one deliberate human edit.
- Keep policy in one place. If the refund window appears verbatim in twelve macros, changing it means twelve edits and at least one miss. Reference the policy article instead.
- Version and date every macro, and assign an owner responsible for reviewing it quarterly.
- Retire aggressively. Any macro unused for 90 days is either badly named or no longer needed.
Keeping macro responses from sounding automated
The complaint customers voice is not that the reply was templated. It is that the reply did not address what they wrote.
Require a personalized opening line that references the specific issue before the macro body begins. Require one deliberate edit inside the body. And write the macros in the same voice the brand uses everywhere else, since a support reply that reads nothing like the rest of the company is its own kind of friction.
Where AI fits alongside macros and SOPs
AI handles the layer below macros: the contacts that never need a person at all. A knowledge base wired into a bot resolves order status, shipping timelines, password resets, and policy questions instantly, which is the same work a well-built macro library was already carrying.
The practical split in 2026 has four parts.
- Deflection. A knowledge base and bot answer repeat questions before a ticket is ever created. This works only if the underlying articles are accurate, which makes knowledge base maintenance a real job rather than a side task.
- Drafting. An AI copilot proposes a reply inside the helpdesk and the rep edits and sends. This compresses handling time on routine contacts without handing the customer relationship to a script.
- Routing and tagging. Automatic classification by contact reason, which is what makes the reporting in the KPI section possible without anyone tagging by hand.
- Summarizing. Thread summaries at escalation and at shift handoff, which is exactly where follow-the-sun teams lose the most context.
Your SOPs and macro library are the source material for all four. Teams that document first get better results from automation, because the system is grounded in approved answers rather than inferring policy from old tickets.
Keep the route to a human obvious and one click away. Contacts that reach a person after a bot are, by definition, the harder ones, so route them to your more experienced reps rather than back into the general queue.
Fiverr’s marketplace demand shows both layers growing rather than one displacing the other. Orders for AI Chatbot Development on Fiverr grew about 10% year over year and Rule-Based Chatbot work grew about 4%, with spend rising on both. Together the two categories accounted for more than 11,000 completed projects over the past year. Over a comparable 12-month window, orders for human customer support grew roughly 150%.
The gap is the useful part. Businesses are adding automation to their support operation at a steady rate while hiring people to run it at a much faster one, which is what a layered model looks like in practice rather than a substitution.
Chatbot figures are based on completed Fiverr orders in Chatbot Development over the 12 months to September 2026.
How to manage multi-channel support across email, live chat, and ticketing
Multi-channel support works when every channel feeds one queue with one set of routing rules. It fails when each channel becomes its own workflow with its own owner, because that is how a customer gets three different answers to the same question.
Email and ticketing
Email remains the default channel for both e-commerce and SaaS, and it is where the gap between customer expectation and delivery is widest. SuperOffice's customer service benchmark study of 1,000 companies put the average response time to a customer service request at 12 hours and 10 minutes, well beyond what most customers consider reasonable.
Treat email and helpdesk ticketing as one channel with one clock. Route by contact reason using tags applied at intake, either by form fields, by automation rules, or by the rep who triages. Set an internal target well inside your public commitment so there is room to absorb a spike.
Live chat
Live chat is a real-time commitment, so staff it as one. It requires a rep who is present and not simultaneously working a complex ticket, because a chat that goes quiet mid-conversation is worse than no chat at all.
Two rules keep chat sustainable at small scale. Cap concurrent chats per rep at two or three depending on complexity. And publish honest chat hours, with a clean fallback to a ticket form outside them, rather than leaving a widget open that nobody is watching.
Phone and social
Phone is worth staffing when contacts are high-value, high-emotion, or complex enough that back-and-forth is inefficient. For most early-stage teams it is a callback offer attached to escalations rather than a fully staffed line.
Social messages need to route into the same queue as everything else. They are public, they carry a faster expectation than email, and they are the channel most likely to be handled by whoever noticed it, which is exactly the pattern that produces inconsistent answers.
One queue, one set of rules
Whatever channels you run, hold these constants:
- One system of record. Every contact creates a ticket, including phone calls and social messages.
- One customer view. A rep answering a chat can see the email thread from yesterday.
- Routing by contact reason and priority, not by whoever is idle.
- A written rule for channel switching, so moving a conversation from chat to ticket preserves history and ownership.
Which customer support KPIs to measure: CSAT, first response time, and resolution rate
Three KPIs give you a complete enough picture to run a support team: CSAT tells you how it felt, first response time tells you how fast the team started, and resolution rate tells you whether the work actually finished. Each one is misleading alone, which is why they are reviewed together.
KPI
What it measures
How to calculate
Common failure mode
CSAT
Satisfaction with a specific interaction
Positive responses divided by total responses, as a percentage
Low response rates skewed toward the very happy and very angry
First response time
Speed of the first human reply
Median time from contact to first reply, measured in business hours
Fast, useless holding replies that game the clock
Resolution rate
Share of tickets actually closed
Tickets resolved divided by tickets received in the period
Tickets closed for inactivity counted as resolutions
First contact resolution
Share resolved without a follow-up
Tickets resolved on the first reply divided by total resolved
Pressure to close prematurely, which raises reopen rates
Reopen rate
Quality check on the three above
Reopened tickets divided by resolved tickets
Ignored entirely, which lets a resolution rate look better than it is
Occupancy
Share of logged-in time spent handling contacts
Contact-handling time divided by available time
Treated as a productivity target rather than a health limit.
Reading CSAT correctly
CSAT measures a single interaction, not the relationship. Send the survey immediately after resolution, keep it to one question plus an optional comment, and watch response rate alongside score.
The number is only useful segmented. CSAT by contact reason shows you which parts of the product or fulfillment process are generating unhappy contacts. CSAT by channel shows you where your coverage promise is failing. A blended score tells you almost nothing actionable.
Setting a first response time target
Set first response time per channel, measured in business hours, and use median rather than mean. A handful of tickets that sat over a weekend will drag a mean badly enough to hide normal performance.
Guard against the obvious gaming risk. If the target is aggressive and the team is stretched, the rational move is to send a fast acknowledgment that resolves nothing. Pair the target with reopen rate and first contact resolution so speed cannot be bought with empty replies.
If part of your queue is answered by automation, report human-handled first response time separately. Blending instant bot replies into the average makes the team look faster than it is and hides a staffing gap that only shows up when something goes wrong.
Making resolution rate trustworthy
Define resolution before you measure it. Decide explicitly whether auto-closed inactive tickets count, whether tickets waiting on the customer count, and whether an escalation to engineering counts as resolved by support.
Then track reopen rate next to it. A resolution rate climbing while reopen rate climbs with it means tickets are being closed, not solved.
How to run support QA beyond CSAT
CSAT tells you what customers noticed. QA tells you what they did not. A customer can rate an interaction highly after a friendly, confident, completely wrong answer, which is why satisfaction scores cannot carry quality on their own.
A workable QA framework has four parts.
- A scorecard. Five to seven dimensions, each scored against a written standard: accuracy, adherence to the SOP, completeness, tone, correct tagging and logging, and escalation judgment. Keep it short enough that one review takes ten minutes.
- A sample per rep. Four to six conversations per rep per month is enough to see a pattern at small team sizes. Sample across contact reasons and channels rather than pulling only escalations, or you will only ever review the hard days.
- Calibration. Have two reviewers score the same conversations monthly and compare. Scoring that drifts between reviewers makes the whole exercise unusable, and the drift stays invisible until you check for it.
- Coaching attached to the score. A number with no conversation after it changes nothing. Each review ends with one specific thing to do differently, and the next review checks whether it happened.
Read QA alongside CSAT rather than instead of it. Where QA scores are high and CSAT is low, the problem is usually policy or product rather than the rep. Where CSAT is high and QA scores are low, you have a friendliness culture sitting on top of inaccurate answers, which surfaces later as reopened tickets and refund disputes.
Run QA on external specialists exactly as you run it internally. A shared scorecard is what holds quality consistent across a team that is not all in one place.
How often to review
Weekly for the working metrics, with a sample of five to ten real conversations read alongside the dashboard. Monthly for QA scorecards, reviewer calibration, and the trend segmented by contact reason and channel. Quarterly for structural decisions: coverage windows, headcount, access reviews, and whether the macro library still matches how the product works.
How to design coverage windows for 24/7 customer support
Coverage design starts with demand shape, not with an aspiration to be always on. Draw the hourly contact curve, decide what each block genuinely requires, and staff to that rather than to a flat 24/7 promise you cannot keep evenly.
Four models cover most situations.
Model
How it works
Best suited to
Extended hours
One team covering a long window, usually 12 to 14 hours, via staggered shifts
Teams whose demand concentrates in one or two adjacent regions
Follow-the-sun
Regional coverage handing off at shift boundaries, each working local daytime
Global customer bases, SaaS products with international accounts
Core plus on-call
Business hours staffed, off-hours monitored with defined severity triggers
SaaS teams where overnight contacts are rare but occasionally urgent
Peak-shaped cover
Additional specialists added for specific windows: weekends, evenings, launches, seasonal peaks
E-commerce with concentrated weekend and promotional spikes
Making follow-the-sun work
Follow-the-sun gives round-the-clock coverage without asking anyone to work nights, since each regional team handles the queue during its own daytime hours. The model succeeds or fails at the handoff.
Build the handoff explicitly:
- Overlap the shifts by at least 20 to 30 minutes so the transition is a conversation and not a silent inbox transfer.
- Require a written handover on every open ticket above a defined priority, covering what was tried and what the customer was told.
- Assign ownership per ticket, not per region, so nothing sits unclaimed in a window where two teams both assume the other has it.
- Give every region the same decision rights. A team that cannot approve a refund at 3am is not really covering that hour.
- Standardize the tooling and the SOPs. Different regions running different processes produces different answers to the same question.
When extended hours beat 24/7
For most e-commerce stores and early-stage SaaS products, extended hours plus a clear off-hours autoresponder outperforms thin 24/7 coverage. A staffed 7am to 9pm window with a stated next-reply time is a promise you keep. A 24/7 badge backed by one overnight person handling three channels is a promise you break at the worst possible moment.
Move to genuine round-the-clock coverage when overnight contacts are consistently urgent, when a meaningful share of revenue sits in a distant time zone, or when your service commitment contractually requires it.
How to design coverage the team can sustain
Support carries one of the highest attrition rates of any operational function, and most of the causes are scheduling decisions rather than personality. A coverage plan that ignores this produces a rota that works on paper for about four months.
Design against the known causes:
- Cap concurrency. Two to three live chats at once is workable. Five is not, and the quality drop shows up in reopen rates long before anyone raises it.
- Protect queue-free time. Blocks for documentation, macro maintenance, and training, scheduled deliberately rather than fitted into gaps that never appear.
- Rotate the unpleasant hours. Weekend and holiday coverage permanently assigned to the same person is a resignation with a delay on it.
- Keep on-call bounded and rare. A documented severity scale keeps overnight contact to genuine emergencies, and a rotation keeps one person from carrying every one of them.
- Give reps a route out of a hostile conversation. A named person to hand it to, with no penalty for using it.
- Watch occupancy, not just volume. Sustained occupancy above roughly 85% leaves no recovery time between contacts and reliably precedes attrition.
This is also the strongest operational argument for flexible coverage. Overnight and weekend blocks staffed by specialists who work those hours in their own daytime, by choice, cost the core team nothing in attrition.
When to hire customer care specialists instead of building in-house
Bring in external specialists when the coverage need is real but the shape does not justify a full-time internal role. That is most often the case for evenings, weekends, overnight windows, seasonal peaks, launch periods, and any single-language or single-channel gap.
The signals that it is time:
- Response times slip consistently during a specific, predictable window rather than randomly.
- Your existing team is covering off-hours informally, which reliably ends in attrition.
- A seasonal peak is approaching that will double volume for a few weeks.
- You need a channel or language you cannot staff internally, such as live chat during APAC hours.
- Founders or product staff are still absorbing overflow tickets.
How to compare the cost of in-house and flexible coverage
Compare fully loaded cost per covered hour, not salary against an hourly rate. Those are different numbers, and the gap between them is where most staffing decisions go wrong.
For an internal hire, the fully loaded figure includes salary, employment taxes and benefits, recruiting cost, the helpdesk seat and tooling, management time, and the ramp period before the person is productive. Divide it by the hours they actually cover rather than the hours they are employed, since holiday, sick leave, training, and meetings all come out of coverage.
For flexible coverage, the comparable figure is what you pay for the engagement divided by the hours it covers, plus your own onboarding time and the QA overhead of managing someone outside the company.
Then apply the utilization test. A window needing sustained coverage across most of a working week supports a full-time hire. A window needing four hours a night, or Saturdays and Sundays only, or six weeks around a seasonal peak, does not, and filling it with a full-time role means paying for capacity you are not using.
Two costs get left out on both sides. On the internal side, the cost of the coverage gap itself: tickets sitting overnight, weekend backlogs, and the response times they produce. On the external side, the cost of documentation, since a specialist without SOPs takes longer to become useful and produces less consistent answers.
Fiverr offers transparent, upfront pricing with flexible engagement structures, which makes cost per covered hour straightforward to work out before you commit to a window.
Fiverr provides access to customer care specialists across time zones, channels, and helpdesk platforms, with varied engagement structures that suit both a defined project and an ongoing arrangement. That range is what makes a hybrid model practical: a small permanent core holding product knowledge and escalation authority, with specialists layered on for the coverage windows and volume peaks that would otherwise force a premature full-time hire.
Customer care is also one of the faster-growing areas of the marketplace: completed orders grew roughly 150% year over year, while the median order value was unchanged, so the increase reflects more businesses hiring rather than a shift in what the work costs. Engagements frequently continue past the first project. Just over a quarter of clients place a follow-on order with the same professional within 90 days, and clients who keep working with the same professional for three or more months account for a little over half of all spend in the category, at a median of six orders each.
These figures are based on completed Fiverr orders in Customer Service over the 12 months to August 2026.
What to look for when hiring
Prioritize in this order for a support role:
- Relevant domain experience. Someone who has handled e-commerce returns or SaaS billing questions ramps faster than a strong generalist.
- Platform familiarity. Experience with your specific helpdesk or e-commerce platform removes a week of onboarding.
- Written communication quality. Support is mostly writing. Ask for a sample reply to a realistic difficult ticket.
- Time zone fit for the block you are staffing, confirmed in writing rather than assumed.
- Comfort working to documented process, since a flexible team depends on people executing the SOP rather than improvising.
How to onboard external specialists well
Give them the same onboarding you would give an employee, compressed. Access to the helpdesk and knowledge base, the SOP set, the macro library, a named escalation contact, and a defined scope covering which decisions they can make alone.
Then run a shadow period. Have them draft replies for review before going live on the queue, usually two to three days for e-commerce contact reasons and a week for technical SaaS support. The review pass is also your fastest signal of whether your SOPs are actually clear.
How to give external specialists access safely
Give the narrowest access that lets the work happen, and set it up before the first shift rather than after the first blocked ticket. Support touches order history, contact details, and sometimes payment metadata, so access design belongs inside onboarding rather than in a separate compliance exercise.
A workable baseline:
- Use role-based access in the helpdesk rather than sharing a login. Named accounts are what make an audit trail possible at all.
- Limit what the role can see. Most support work needs order status, contact history, and fulfillment detail. It rarely needs full payment data, and most helpdesk and e-commerce platforms mask card details by default. Keep it that way.
- Separate viewing from acting. Refunds, cancellations, and account changes above your threshold can require a second approval without slowing routine replies.
- Put the data terms in writing before access is granted: what can be accessed, where it may be stored, what happens at the end of the engagement, and confidentiality terms.
- Keep customer data inside the helpdesk. No exporting ticket lists to personal spreadsheets, no screenshots pasted into chat threads.
- Revoke access the day an engagement ends, and review the full access list quarterly. Stale accounts are the most common finding in any access review.
If you sell into the EU or UK, personal data handling carries specific obligations, and if your support process touches cardholder data, so does that. Confirm what applies to your business with whoever owns compliance before you extend access outside the company.
Common problems when scaling customer support
Most scaling failures repeat in the same handful of patterns.
Channels fragment into separate inboxes. Symptoms are duplicate replies and contradictory answers. Fix by routing every channel into one system of record and reporting only from that system.
The macro library goes stale. Symptoms are customers quoting outdated policy back at you. Fix with named macro owners, quarterly reviews, and policy referenced in one place rather than duplicated.
Coverage exists on paper but not in practice. Someone is technically online at 2am but lacks the access or authority to resolve anything. Fix by auditing decision rights per coverage block, not just presence.
Access outlives the engagement. Accounts stay live after a specialist finishes, usually because nobody owns offboarding. Fix by setting the revocation date at the moment access is granted, and reviewing the full list quarterly.
KPIs improve while customers do not. First response time drops and resolution rate rises while reopen rate quietly climbs. Fix by reviewing the three metrics together and reading actual conversations weekly.
Automated deflection is counted as resolution. Contacts a bot closed without answering look identical in the dashboard to contacts that were solved. Fix by tracking containment and the rate at which deflected customers return within 48 hours, separately from human resolution rate.
Escalations have no owner outside business hours. Tier two is a person, and that person sleeps. Fix with a documented severity scale and a named on-call contact per window.
Seasonal peaks are staffed reactively. Hiring starts when the queue is already backed up, by which point onboarding is happening under pressure. Fix by scheduling flexible coverage against last year's volume curve, with specialists onboarded two to three weeks before the peak begins.
Build the customer care team your growth actually needs
Fiverr connects businesses with customer care specialists across support channels, helpdesk platforms, and time zones. Whether you need someone to document your SOPs and build a macro library from scratch, cover weekend and overnight windows, staff live chat during a product launch, or set up ticket routing and reporting in your helpdesk, you can find professionals with the specific operational experience your team is missing. Flexible engagement structures mean you can start with a defined scope and extend into an ongoing arrangement where the coverage need proves out.
Ready to scale your customer care team?
Hire support specialists for any channel or shift.

FAQs
Most growing teams do both. Keep a small in-house core holding product knowledge, escalation authority, and quality standards, then use external specialists for the coverage windows and volume peaks that would not justify a full-time role. Compare fully loaded cost per covered hour rather than salary against a rate, and check whether the window needs sustained coverage or only a few hours a day.
Related Guides

About the author
Yaara Yohanan RozenDirector of Global Customer Support
Yaara Yohanan Rozen is the Director of Global Customer Support at Fiverr, where she leads worldwide support operations and multi-channel care teams. With over 20 years of executive experience in CX and global operations management, she specializes in building the flexible, data-driven support architectures this guide discusses. Yaara excels at translating Voice of the Customer (VoC) insights into scalable SOPs, optimizing global coverage models, and empowering teams to maintain exceptional service quality as contact volumes grow.
